TRANSMISSION // 2611.04264v1
Query-Matching Documents Can Crowd Out Evidence in RAG Retrieval
Source published
A preprint finds that documents tailored to a query can enter retrieval results and displace relevant evidence, even without malicious instructions. Tests across two benchmarks also show that filtering suspiciously high query overlap can remove legitimate material.
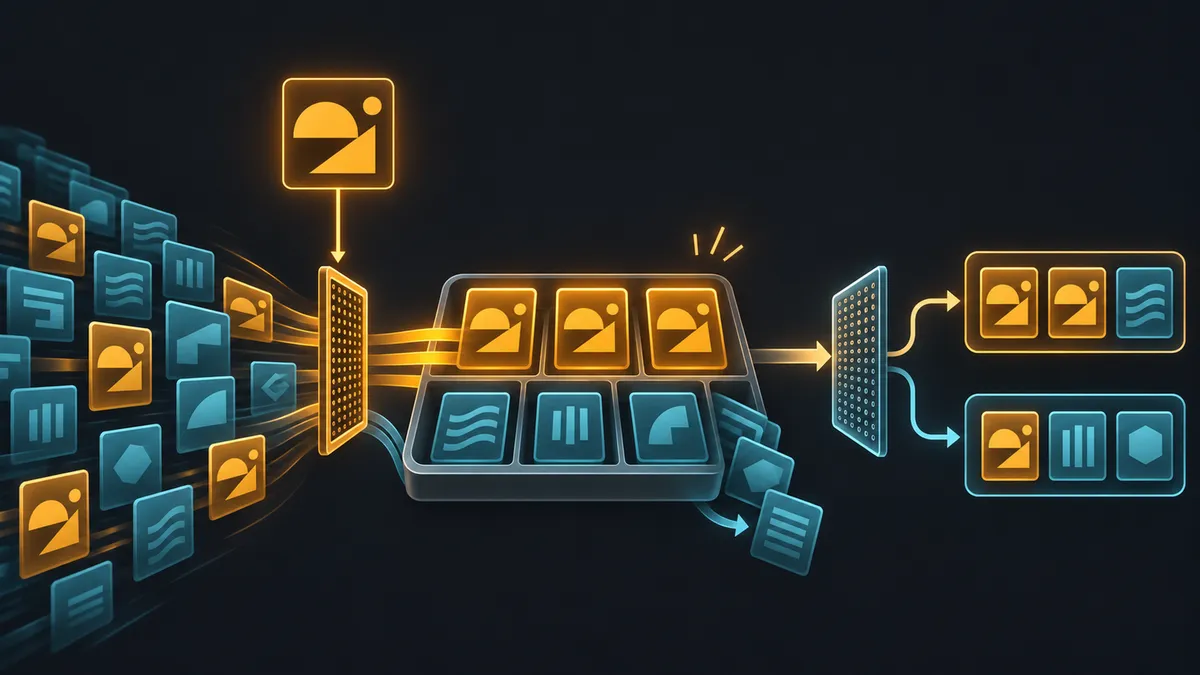
Before an outside document can influence a retrieval-augmented language model, it must be selected as evidence. This study examines that selection boundary—and finds that matching the question can matter more than the malicious text attached to it.
A retrieval-augmented generation system, or RAG system, searches an external collection before passing selected documents to a language model. That creates a boundary worth testing: can an attacker get deliberately planted material into the retrieved evidence, even without changing the question or the search system?
A November 2026 preprint by Janet Sung and colleagues investigates that boundary. Its experiments measure which documents are retrieved and how legitimate evidence is displaced. They do not test whether a language model follows malicious instructions or produces an incorrect answer.
Separating query matching from malicious content
The researchers evaluated 623 queries across two public BEIR benchmarks: SciFact, with 300 queries, and NFCorpus, with 323. They tested BM25, a term-based retriever; latent semantic analysis, or LSA; and a Hybrid system combining their rankings. A separate validation used the pretrained BGE-small dense retriever.
In the isolated-target experiments, each query faced only its own planted documents. The attacker could add indexed material but could not change clean documents, relevance labels, queries or retriever parameters. The classical retrievers used statistics fitted to the clean collection, keeping those statistics fixed when documents were added.
Crucially, the study compared documents containing just the query with versions that appended standardized injection payloads or neutral text. This helped distinguish the effect of matching a question from the effect of the appended material.
For BM25, full-query matching explained nearly all the observed degradation. Appended text also changed LSA and Hybrid rankings, but neutral additions changed them too. The results therefore support an effect from appended-content identity—not a demonstrated retrieval mechanism specific to malicious instructions.
Five targeted documents can change the evidence
With five query-plus-payload documents per target, isolated experiments reduced ranking quality, measured by nDCG@10, by 40.2–61.5% across the classical retrievers and datasets. This metric rewards relevant documents appearing near the top of the first ten results.
For Hybrid retrieval, SciFact nDCG@10 fell from 0.465 to 0.183; NFCorpus fell from 0.267 to 0.160. At least one target-specific poison appeared in the top ten for every SciFact query and 91.0% of NFCorpus queries.
Five documents represented only about 0.10% and 0.14% of the respective contaminated collections. But these were not random additions: they were written specifically for the query under evaluation. The small collection-wide fraction therefore came with strong targeting knowledge.
The dense-retriever validation reinforced the importance of that targeting. Five query-only documents produced 100% target exposure on both datasets. Adding injection payloads barely changed SciFact ranking quality and slightly reduced NFCorpus exposure, to 98.8%. Malicious text was not needed to obtain high admission rates in these conditions.
Partial knowledge needs a denominator
The researchers also tested documents anchored by two or four query terms. A fixed term count, however, does not represent a fixed amount of information. NFCorpus queries averaged only 2.48 eligible terms, so two terms often revealed the entire eligible query.
A subset of 162 longer SciFact queries offered a clearer partial-information test. Two randomly selected terms covered an average of 19.9% of eligible terms, yet produced 39.5% Hybrid target exposure. Four terms covered 39.7% and produced 89.5% exposure.
When every evaluation query contributed poisons to one shared collection, contamination became much broader: five documents per target accounted for 22.45% of SciFact and 30.77% of NFCorpus. Documents aimed at other queries also entered results, making target-specific exposure alone an incomplete measure.
Filtering has an evidence cost
An admission rule rejected documents with sufficiently high weighted coverage of query terms. At a 0.95 threshold, it eliminated target exposure under full-query Hybrid stress on both datasets. But repeating the query makes these poisons especially well matched to that rule; this was not evidence of a general-purpose detector.
The collateral cost differed sharply. Clean SciFact nDCG remained relatively close to its unfiltered value, while clean NFCorpus nDCG fell from 0.267 to 0.134. Stronger rejection also suppressed partial-query poisons but removed much more legitimate retrieval utility. Diversity reranking with maximal marginal relevance changed ranking quality without reducing exposure in the tested configuration.
The findings remain bounded by two benchmarks, incomplete relevance judgments and one compact pretrained dense model. Their practical message concerns retrieval evaluation: measure poison admission alongside retained evidence and clean-task quality. None of those measurements, by itself, establishes whether a downstream language model will be successfully manipulated.
- retrieval-augmented generation
- corpus poisoning
- retrieval reliability
- query anchoring
- evidence displacement
- admission control