TRANSMISSION // 2611.04203v1
More platforms do not guarantee better AI recommendations
Source published
A preprint models personal recommendation agents comparing offers from competing platforms. Learning from consumed items can counter exaggerated claims, but benefits depend on resource quality, feedback budgets and how simulated user value is measured.
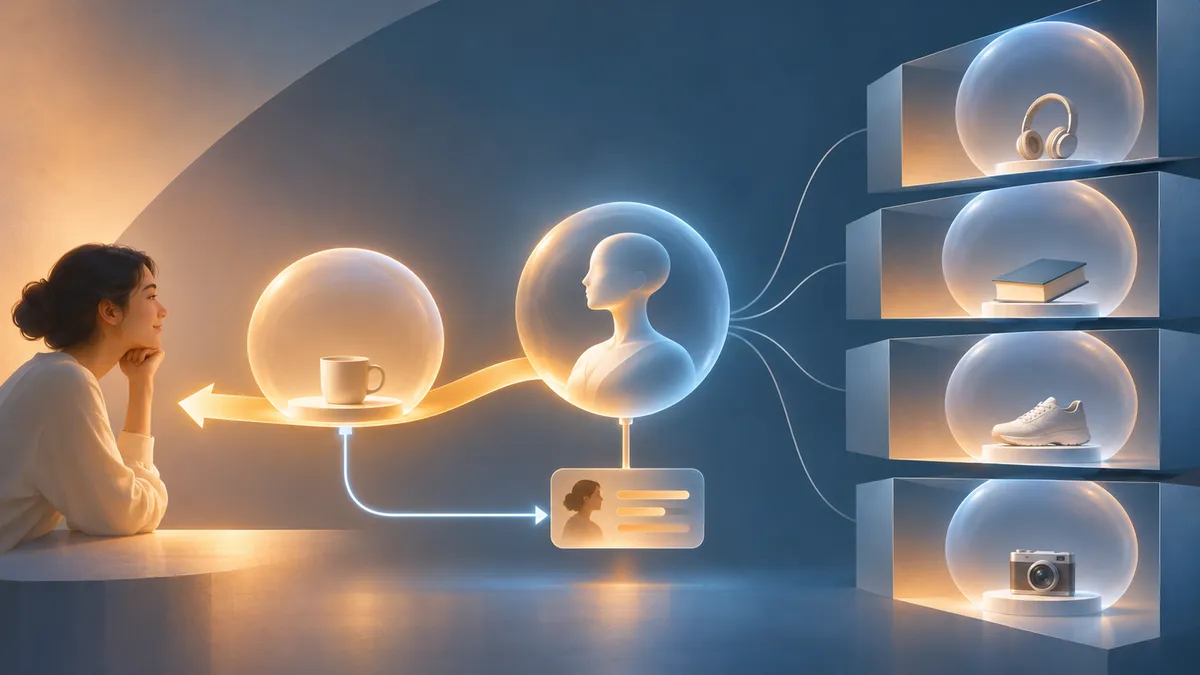
A personal AI agent could compare recommendations across platforms instead of keeping users inside one catalog. But broader access brings another problem: competing platforms can exaggerate their offers, while users can verify only what they consume.
A personal recommendation agent that searches several platforms might find better options than any single platform offers. Yet access alone does not guarantee better choices. A preprint by Kehan Zheng and colleagues at Tsinghua University and Tencent examines how exaggerated platform claims and limited personal feedback can undermine that promise.
Posted on November 3, 2026, the study combines mathematical analysis with simulated markets. Its central conclusion is conditional: credibility assessment can help users benefit from competition, but more platforms also create more claims to check.
Comparing claims with experience
The researchers model repeated interactions between personal user agents and competing platform agents. Each platform retrieves a candidate from its private resources. It can inflate the candidate’s reported relevance, but cannot change the underlying item or its actual value through that reporting action.
The model represents exaggeration with a single numerical intensity. At one extreme, a platform reports the true relevance; at the other, it reports the maximum possible relevance regardless of the item’s value. This is an abstraction of strategic presentation, not an experiment in generating persuasive product descriptions.
Each user agent subtracts a personal credibility correction from every platform’s report. Selection remains probabilistic: higher corrected scores are favored, but lower-scoring candidates can still be chosen. After consumption, the agent observes the selected item’s exact value and updates only that platform’s correction, using an exponentially weighted average of verified overstatement. Unselected records remain unchanged.
Platforms seek engagement weighted by the value they deliver. Users are evaluated by consumed value, not by reported relevance or the random influences on selection.
Why competition can disappoint
Without credibility updates, the authors identify a weak Nash equilibrium in which every platform always reports maximum relevance. No platform can improve its payoff by changing its own policy alone when all rivals follow that strategy. Identical reports produce uniform selection, removing the advantage of favoring better candidates. The result does not show that learning platforms necessarily converge to this equilibrium.
To separate access from reporting, the study introduces a reference system that uses true relevance while retaining the same randomness in choice. Even this accurately informed system can perform worse than the original platform: adding weaker candidates can increase the chance of consuming something inferior.
Credibility assessment provides a mathematical safeguard under an additional restriction. For each user–platform pair, the difference between reported and actual relevance must remain within a bounded range over the evaluated period. Persistent exaggeration is allowed; sufficiently large changes can make the guarantee uninformative.
The bound separates a temporary verification cost from a remaining allowance for changing discrepancies. With fixed mechanism settings and a fixed positive margin between the accurately informed gain and that allowance, an interaction budget proportional to platform count suffices to reach at least the original platform’s expected average utility.
This is not a safety guarantee for every person or every realized interaction. A constructed cold-start market also shows why early losses matter: users can initially do worse despite having access to a superior resource. The matching linear-budget result concerns this particular mechanism and reporting family, not all possible recommendation agents.
Different simulated markets, different outcomes
The main experiments used 128 users, 4,096 rounds and 12 random seeds, testing markets containing two to 32 platforms. Platform behavior included fixed exaggeration, maximum exaggeration and learning among five reporting intensities.
In synthetic markets with 16 platforms and learning platforms, credibility assessment produced an average gain of about 0.048 over the original platform, with a pointwise 95% interval of approximately 0.039 to 0.058. Without assessment, the mean gain was negative. Nevertheless, about one-third of users still lost relative to their original platform.
The Amazon-grounded results were less favorable. The researchers clustered embedded product descriptions from the Musical Instruments dataset into virtual catalogs. These were simulated platforms, not observed competing sellers. Item value was defined by semantic similarity to simulated queries, rather than measured consumer satisfaction.
With learning platforms at the default settings, assessment improved on uncorrected reports, but the mean gain over the original platform remained negative. Its interval, −0.0160 to 0.0004, included zero, establishing neither average benefit nor harm against that baseline.
Replacing semantic relevance with a rating-trained prediction model yielded positive average gains. However, that predictor was not demonstrably better than a bias-only model on the reported error measure. Neither proxy establishes actual consumer welfare.
The preprint therefore supports credibility correction as a useful mechanism within its modeled setting, not a universal endorsement of platform competition. Its guarantees assume fixed resource-generation rules, numerical reports, exact feedback on consumed items and bounded discrepancy variation. Better access helps only when the available advantages survive both imperfect choice and the cost of learning whom to trust.
- agentic recommendation
- platform competition
- credibility assessment
- recommender systems
- user welfare
- game theory
- consumption feedback