TRANSMISSION // 2611.04113v1
How Worse Model Variants Can Still Guide Better AI Training
Source published
A preprint investigates why evolution strategies can improve a neural network even when every randomly perturbed version performs worse than its parent. Experiments and a simplified mathematical model suggest that relative scores still reveal useful directions, while combining many perturbations reduces unwanted movement. The findings concern specific training tasks, not a general guarantee of better performance or efficiency.
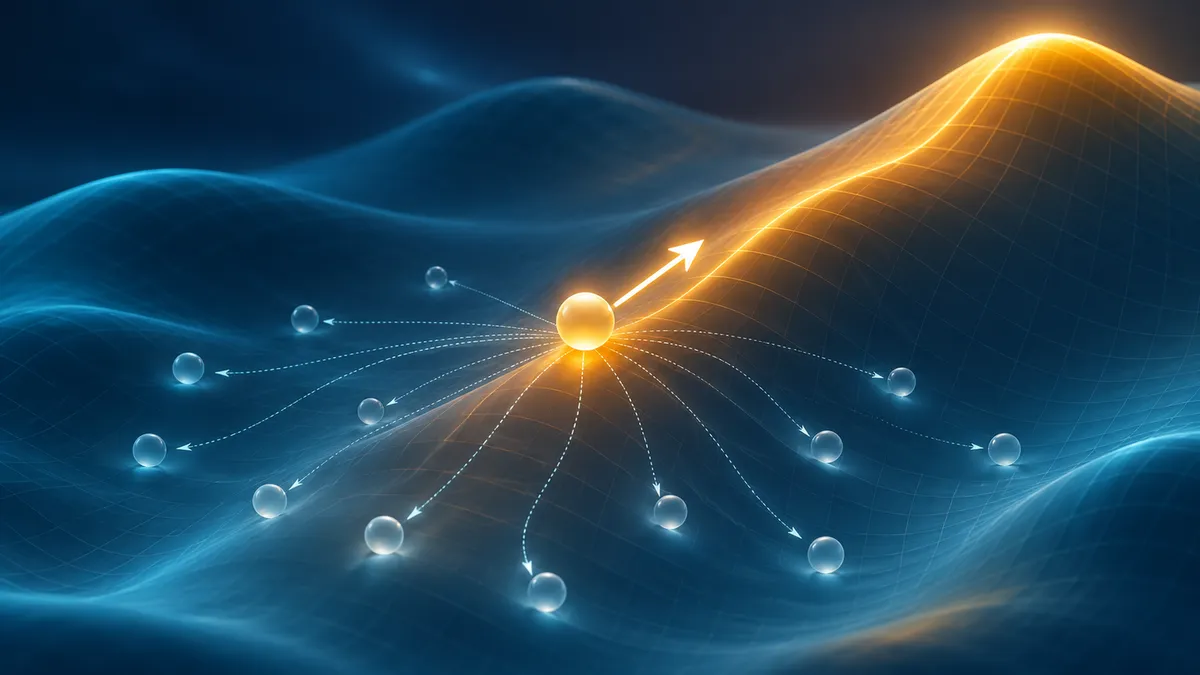
Randomly changing an AI model’s parameters usually sounds useful only if some changes improve it. A new preprint examines a counterintuitive alternative: unsuccessful variants can collectively supply information for a successful update, without any of them becoming the next model.
An apparent contradiction in model training
In The Evolution Strategies Paradox: Better Models from Worse Perturbations, Roberto Dailey and colleagues investigate training runs in which a parent neural network improves while nearly all its randomly modified offspring score worse. The November 2026 preprint comes from researchers at Cognizant AI Lab and the University of Texas at Austin.
The apparent contradiction disappears once the offspring’s role is understood. The method does not simply replace the parent with its best offspring. Instead, it combines information from their relative performance to construct a different update. A candidate can be worse than the parent yet still provide useful evidence about which direction to move.
How the experiments worked
The researchers used evolution strategies, or ES, with random Gaussian perturbations to model parameters. Each iteration generated a population of modified models and evaluated their rewards. Scores were standardized by subtracting the population mean and dividing by its standard deviation. The next update averaged the perturbation directions, weighted by those standardized scores.
Consequently, an offspring that performs better than its peers receives a positive weight even if it performs worse than the parent. Exploration size and update size are controlled separately: the final model need not move as far as the offspring did.
The detailed language-model experiments used Qwen 2.5 7B-Instruct on 4×4 Sudoku and Countdown tasks. Each ran for 500 iterations with 30 offspring per iteration, a perturbation scale of 0.001 and a learning rate of 0.0005. Evaluation used temperature-zero generation and a fixed set of 800 problems per task, with the entire set serving as each training batch.
The paper also illustrates the phenomenon with OLMo 2 7B and a randomly initialized, approximately 60,000-parameter convolutional network trained on MNIST. Across the examples, offspring initially sometimes outperformed their parent, but that fraction fell to or near zero during extended periods of improving parent performance.
Why worse candidates remain informative
To examine what changed during training, the team sampled 300 perturbation directions at model checkpoints and evaluated them across several perturbation magnitudes.
At the starting model, increasing perturbation size mainly increased reward variation. Later in training, larger perturbations also consistently reduced average reward. This supports the authors’ explanation that local curvature makes sufficiently large random moves costly.
Yet the same directions often retained positively correlated rewards across small and large magnitudes. Directions that looked relatively promising nearby tended to remain relatively promising farther away, even where their absolute scores were poor. Correlations generally weakened as the difference in magnitude grew.
The authors connect this behavior to high-dimensional geometry. Gaussian perturbations in spaces with many parameters have nearly equal lengths. Under approximately isotropic curvature, they therefore encounter a similar curvature penalty, leaving relative scores able to reveal directional differences.
A separate experiment followed only the best of 30 perturbations, scaled down to the size of a typical ES update. That approach improved performance, but the weighted ES combination performed better. This supports an additional benefit from aggregation rather than selection alone.
Combining signal while reducing noise
The mathematical analysis separates an update into movement along the local reward gradient and movement perpendicular to it. In the simplified model, averaging preserves the expected useful component while reducing the perpendicular component approximately in proportion to the inverse square root of population size.
The analysis also incorporates observation noise and a locally quadratic reward landscape. Although temperature-zero outputs were deterministic, measured reward varied sharply over very small parameter changes. The authors model this fine-scale irregularity as observation noise, rather than attributing it to random generation.
This produces a tradeoff. Perturbations that are too small provide a weak directional signal relative to reward irregularities. Perturbations that are too large introduce curvature-related variation that obscures that signal. In the reported Sudoku comparisons, intermediate scales trained better than smaller scales that produced more individually improving offspring.
Population-size experiments likewise showed increasing average update gains followed by a plateau, alongside decreasing update magnitudes, consistent with the proposed mechanism.
What the findings do not establish
The detailed language-model analysis centers on two tasks and fixed training sets. Larger batches made the paradox more prominent. These observations do not establish generalization to unseen problems, universal hyperparameter settings or comparative computational efficiency.
The theory also relies on local landscape assumptions and approximations, including replacing sample reward statistics with population statistics in parts of the derivation. The authors describe their interpretation as a new optimization paradigm; that is a broader claim than the experiments establish. The narrower finding is compelling enough: individually unsuccessful probes can collectively guide useful updates.
- evolution strategies
- large language models
- derivative-free optimization
- Gaussian perturbations
- reward landscapes
- high-dimensional optimization
- AI fine-tuning