TRANSMISSION // 2611.04079v1
AlgoPilot teaches language models to choose a solving strategy before answering
Source published
An arXiv preprint describes a system that separates strategy selection, structured guidance and execution. The authors report substantial benchmark gains for Qwen3-8B, although stronger comparison prompts narrow its advantage over larger models, and evaluation-format effects complicate interpretation.
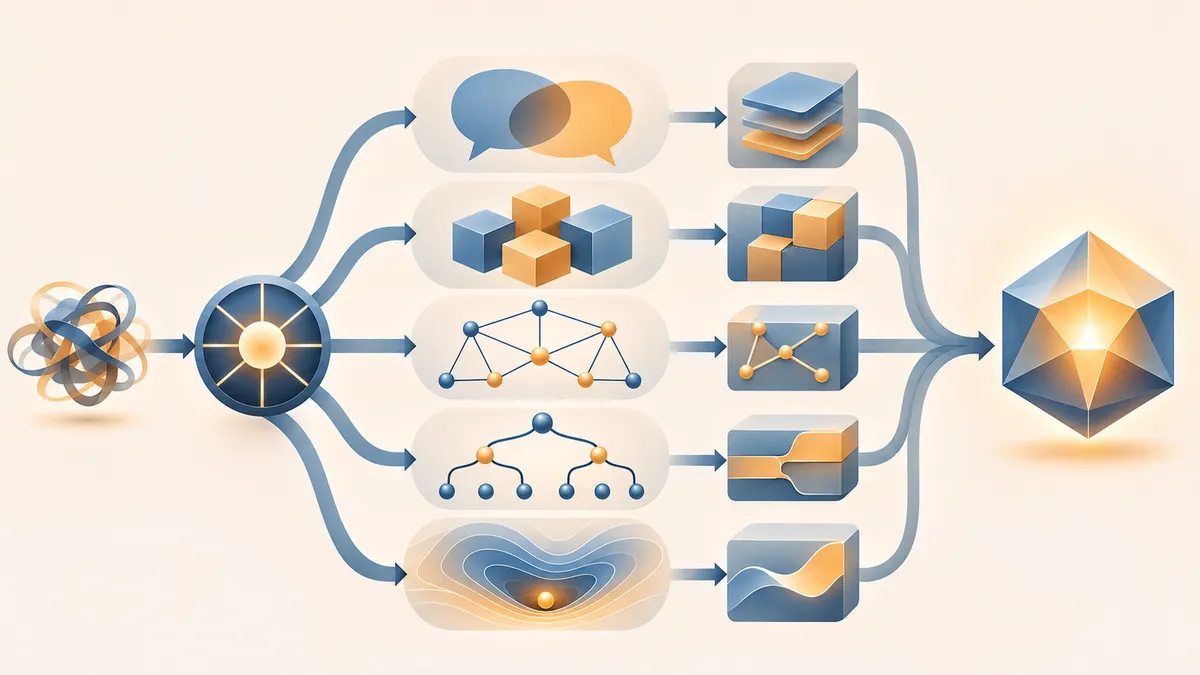
Some problems need an explanation; others need code, a planner or an optimization solver. AlgoPilot attempts to teach language models to choose between these approaches and formulate the problem before solving it.
Choosing how to solve
AlgoPilot starts from a distinction: choosing a method is different from applying it correctly. A scheduling problem, for example, may require both selecting an optimization solver and translating everyday language into variables, constraints and an objective.
In an arXiv preprint dated November 2, 2026, Yilun Hao and colleagues describe a framework that separates those responsibilities. The authors, affiliated with MIT, Harvard University and the MIT-IBM Watson AI Lab, report improvements across coding, textual reasoning, planning, logic and optimization tasks. These are findings reported in a preprint, not independently verified results established by the supplied material.
Three stages, five approaches
First, a model called SteerLM selects a problem-solving approach and decides whether additional guidance is needed. Its choices are natural-language reasoning, executable code, logical constraint solving, symbolic planning and mathematical optimization.
If guidance is selected, a specialist GuideLM prepares a structured formulation. For optimization, this includes decision variables, their bounds, an objective and constraints. For planning, it identifies objects, states, actions and goals. Coding guidance instead emphasizes an algorithm, implementation steps, edge cases and potential mistakes.
Finally, ExecuteLM uses the original question, selected strategy and optional guidance to generate an answer or an artifact for execution. In the main experiments, the executor is an unmodified Qwen3-8B language model. The system therefore adds trained selection and guidance models rather than improving the executor through additional fine-tuning.
Learning from execution
The researchers train the guidance specialists using candidate formulations filtered by downstream correctness. In their initial search, each candidate is tested through five execution attempts; guidance must produce at least three correct outcomes to qualify.
They then evaluate alternative strategies to build training targets for SteerLM. Its supervised training is followed by reinforcement learning using previously collected execution scores. This rewards selecting approaches that worked reliably during data collection without rerunning every solver during reinforcement learning.
The design assumes that suitable executors and correctness checks are available. Its feedback reflects success under those checks, rather than providing a general guarantee that a model has understood a problem.
What the headline score measures
The main evaluation covers 2,220 test problems drawn from 13 benchmarks spanning 66 domains. The authors describe an approximately 22,000-instance collection divided randomly into training, validation and test sets. They generate three solutions per test problem and average their success rates, rather than counting a problem as solved whenever any attempt succeeds.
AlgoPilot scores 72.9%, compared with 38.4% for directly prompted Qwen3-8B: a gain of 34.5 percentage points. These headline averages give equal weight to the five task categories, despite their different numbers of examples.
The largest changes include symbolic planning, where the reported score rises from zero to 91.5%, and optimization, where it rises from 18.3% to 59.6%. Removing either learned steering or guidance substantially lowers the overall result in the authors’ component-removal experiments.
A narrower lead over stronger comparisons
The headline comparison with directly prompted GLM-5 is 72.9% versus 61.2%, an 11.7-percentage-point advantage. However, the appendix contains a stronger GLM-5 baseline that receives the original task category and its corresponding prompt. That configuration reaches 71.5%, narrowing AlgoPilot’s lead to 1.4 percentage points.
Evaluation compatibility also matters. The authors report that some baseline failures occur because models generate code where the evaluation pipeline expects a textual answer, or Python where it expects planning specifications. AlgoPilot largely avoids these mismatches. Its gains therefore should not all be interpreted as improvements in underlying reasoning independent of the surrounding software.
An 81.7% result selects the best measured strategy among three predictions. Because that selection uses observed outcomes, it is a diagnostic comparison, not the standard first-choice performance.
Transfer, costs and remaining errors
On 432 additional problems from held-out domains and unseen benchmarks, the authors report 73.3% instance-weighted accuracy, against 66.2% for the stronger Qwen3-8B prompting baseline. AlgoPilot beats both prompting baselines on five of ten domains, not all ten.
Reusing the trained steering and guidance modules with Gemma-4-E4B-it raises its reported category-average score from 50.8% under reasoning prompts to 60.5%. This demonstrates transfer to one additional executor, not arbitrary models.
The approach is expensive to prepare: the authors report approximately 7,514 GPU-hours for training-data construction alone. Evaluation also requires extra model calls. Incorrect guidance can steer an executor toward a consistently wrong solution, and incorrect answers remain the dominant reported failure type.
There are reporting ambiguities: one appendix table lists original-input overall accuracy as 74.10%, whereas the main paraphrase comparison uses 72.9%. The cost appendix also describes initial guidance search across the full collection, while the experimental section says training data use only the training split; the supplied text does not reconcile those accounts.
The evidence supports learned strategy selection and formulation as promising benchmark techniques, not autonomous decision-making guarantees. The authors recommend human oversight, downstream validation and task-specific safety checks before deployment.
- AlgoPilot
- large language models
- strategy selection
- structured guidance
- symbolic planning
- constraint solving
- mathematical optimization
- reinforcement learning