TRANSMISSION // 2611.04035v1
Recursa improves AI legal research by revising its own working knowledge
Source published
An Alibaba Research preprint reports that AI agents improved performance on a synthetic law-firm benchmark by updating shared instructions, skills and memories. The experiments leave the underlying models unchanged, and the gains depend on automated grading, available feedback and the learning configuration.
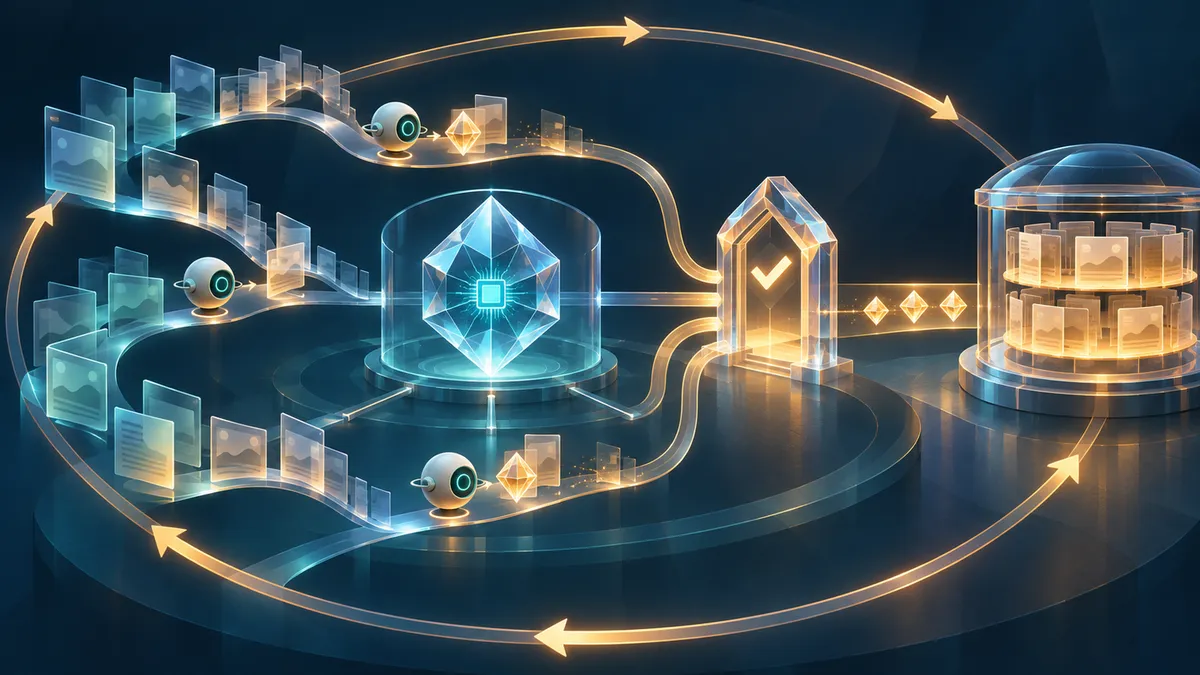
What if an AI assistant could improve by keeping better working notes rather than retraining its neural network? In Recursa: Toward Recursively Self-Improving Foundation Model Systems, Erkang Zhu, Yin Lin, Xiaorong Shi, Xuanrui Lin and Jingren Zhou investigate that approach. Their November 2, 2026 preprint, arXiv:2611.04035v1, reports improvements in legal-research tasks while also showing that additional learning rounds do not reliably produce better results.
What actually improves
Recursa’s central idea is to improve the system surrounding a foundation model, rather than immediately retrain the model itself. The Alibaba Research authors distinguish a knowledge gap—missing facts or unfamiliar document organization—from a behavior gap: having relevant information but applying it incorrectly.
The system maintains a knowledge repository containing instructions, reusable skills and memories of previous attempts and learning decisions. In the reported experiments, only this repository changes. The foundation models and the software that runs them remain fixed. Despite the paper’s broader ambition of recursive self-improvement, it does not demonstrate autonomous improvement of model weights or the execution software.
A shared notebook, refined through experience
Recursa first explores domain materials and builds a navigable map of them. It also generates practice tasks grounded in those materials, attempts them and records lessons. Repository entries retain source references, uncertainty and their applicable scope; they are not intended to replace original documents.
Next, solver agents attempt training tasks while learner agents inspect answers, execution histories and feedback. Learners revise instructions and skills, then retry affected tasks and a sample of previously successful tasks to check for regressions.
A parent learner can divide the workload among child learners, reconcile their edits and record lessons about the learning process itself. This delegation and reflection make the process recursive: learners can coordinate other learners, not merely repeat an answer-generation loop.
The execution layer uses a persistent Python session. Agents can combine searches, filter results and retain intermediate data without putting everything into the model’s active context. Earlier interactions remain in an external event log that agents can query when needed.
The reported results
The evaluation uses Harvey LAB’s Firm Knowledge environment, a synthetic law firm with 46 fictional clients, 266 matters and 9,288 files. Its approximately 108 million tokens support 250 tasks requiring evidence gathering and long-form answers. The researchers split these into 150 training tasks and 100 held-out test tasks.
The strict metric, called all-pass rate, counts a task as successful only when its answer satisfies every grading criterion. Using the authors’ revised rubrics, multi-learner Recursa increased test all-pass performance from 30% without learned repository components to 55% with DeepSeek-V4.1-Flash. With Qwen3.8-Flash, it increased from 35% to 46%. These are gains of 25 and 11 percentage points, respectively—not measures of general legal competence.
Average criterion-level performance increased more modestly: from 80.0% to 84.1% for DeepSeek and from 83.2% to 84.4% for Qwen. The authors interpret this pattern as partially correct answers becoming complete successes.
Initial corpus study mainly improved efficiency. Across all 250 tasks with DeepSeek, bootstrapping reduced average interaction turns from 69.4 to 55.0 and accumulated input tokens per task from 6.45 million to 4.81 million. These figures describe subsequent task attempts, not the total cost of building and refining the repository.
The paper’s examples illustrate procedural changes. One agent learned to search for alternative formulations of a no-shop covenant and inspect their substance rather than rely on clause headings. Another used engagement records to determine which matters belonged to the firm’s intellectual-property practice before checking for settlements.
Why the qualifications matter
The headline scores use automated judgments from Qwen3.8-Max. Although the same underlying model performs solving and repository revision within each learning run, a separate model judges answers. Thus, “without a stronger teacher” does not mean learning without external evaluation signals.
The researchers also revised 46 of 2,623 grading criteria across 30 tasks, including 13 test tasks, after identifying what they describe as conflicts with questions or source documents. They report both rubric versions. Under the original rubrics, the highlighted DeepSeek comparison is 30% to 54%, and Qwen’s is 33% to 45%. Gains therefore remain, but their exact size depends on grading choices.
More learning was not consistently better. DeepSeek’s multi-learner test all-pass rate reached 55% in the second round and fell to 43% in the third. Single-learner configurations performed worse than the highlighted multi-learner configurations, but the paper does not establish a compute-matched comparison. Comparisons with previously published agent systems also use differing evaluation and adaptation procedures.
The evidence is confined to one synthetic legal environment. The paper provides no confidence intervals or repeated-run variability estimates for its headline results. The authors acknowledge substantial computational demands, dependence on corpus quality and underlying model capability, and risks of propagating incorrect or biased information. Experiments used isolated sandboxes and public data. Recursa offers evidence that reusable working knowledge can improve an agent’s performance in this setting—not proof of unlimited, reliable or broadly general self-improvement.
- Recursa
- recursive self-improvement
- AI agents
- foundation models
- knowledge repositories
- legal research
- Harvey LAB
- multi-agent learning