TRANSMISSION // 2611.03930v1
AI memory is useful only when it helps with the task at hand
Source published
A preprint measures how individual stored experiences change an AI model’s answers. On factual-recall tasks, memories containing relevant answers helped more than matched controls, while the tested summaries often lost useful details. The benefits did not extend to the study’s coding benchmarks.
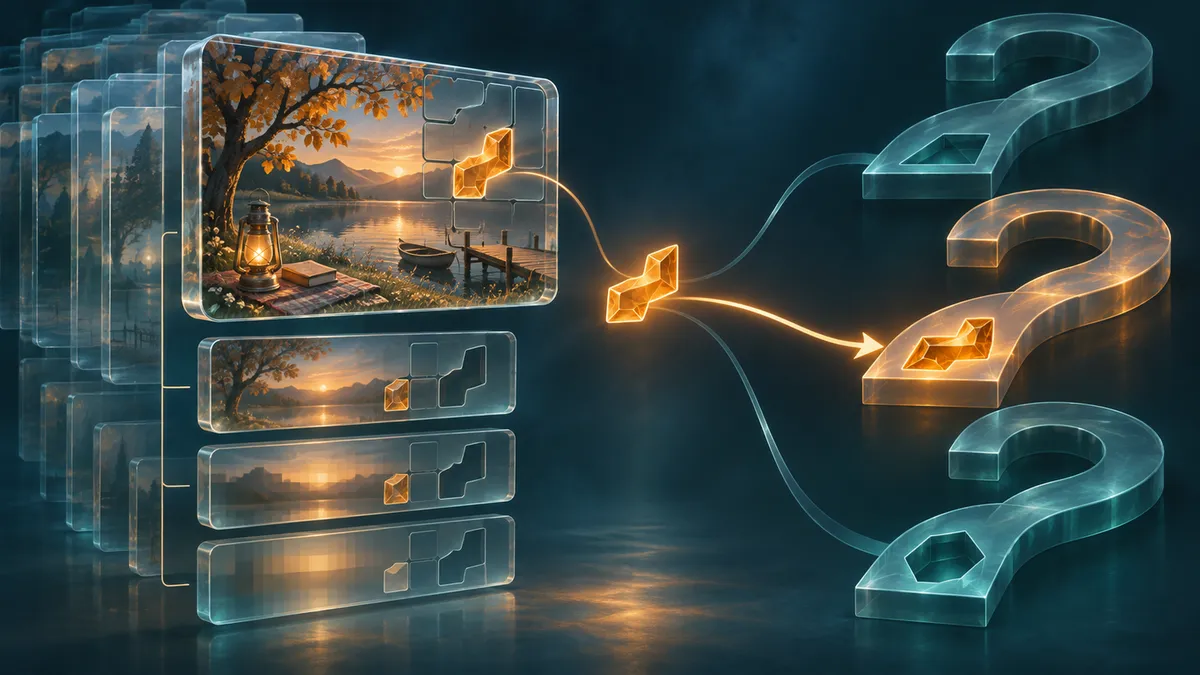
A stored page visit might contain exactly the budget figure an AI assistant needs—or offer little help with its next question. Researchers propose evaluating long-term memory through its effect on specific tasks, alongside the cost of creating and using it.
Measuring what a memory changes
In a preprint posted on November 2, 2026, Chih-Hsuan Yang, Anjir Ahmed Chowdhury, Feng Yan and Rajeev Thakur investigate a practical question: what is a particular stored experience useful for? Rather than assigning each memory one importance score, they measure how its presence changes performance on different tasks.
Their protocol separates memory creation from later evaluation. A writer stores a past experience without seeing the future question. A fixed reader model then answers that question with and without the target memory, using identical background material in both conditions. The difference in task reward measures the memory’s utility under those conditions. A separate ledger records costs, including memory formation, storage, retrieval and exposure to the reader.
A zero difference means no measured reward change—not necessarily identical answers or an absence of useful information.
Relevant answers produce larger gains
The main experiments use LongMemEval-V2, with memories drawn from web-agent page visits. The reader answers factual questions in a single model call; it does not act in an environment. The principal reader and writer are gpt-oss-120b.
The researchers identify “answer-bearing” memory–task pairs using the benchmark’s reference answers and scoring rules. To make the screen selective, a question qualifies only when it matches between one and eight memory units in its domain. This is an experimental screening tool, not a deployable retrieval method: it requires the answer in advance and does not identify every helpful memory.
The executed screened design covers 60 memories and 1,157 memory–task pairs. Each memory faces answer-bearing questions, matched-control questions from the same task family, and randomly selected questions.
For each memory, the team compares its average reward gain on answer-bearing questions with its gain on matched controls. Averaged across memories, that contrast is +0.33, with a 95% interval from +0.21 to +0.46. This is a difference between two memory effects, not a blanket 33-percentage-point improvement for any stored memory.
Even relevant evidence was far from sufficient: the reader answered only 46% of answer-bearing pairs correctly with the memory present.
Compression can discard the useful detail
The study compares three representations of the same experience: unmodified page-visit text, a model-written summary, and a structured record covering fields such as action, outcome and lesson. Neither model-written version sees the future task.
On 277 pairs evaluated under all three representations, the within-memory answer-bearing-versus-control contrast is +0.32 for raw text, +0.06 for summaries and −0.05 for structured records. Only the raw-text interval excludes zero. The shorter versions expose far fewer tokens, but often omit the information needed to answer the question.
A separate truncation experiment finds that smaller text budgets retain less answer-bearing content and yield smaller gains. Because truncation changes both length and content, this supports—but does not prove—the explanation that preserved answer information drives the difference.
Raw text also performs better in an exploratory experiment that equalizes total context length by padding shorter conditions with additional background material. The reported comparison excludes pairs exposed to a disclosed cache-key defect. The finding is specific to the tested writers and prompts; the structured format emphasizes procedural lessons, and the authors note that a writer instructed to preserve values and identifiers might retain more relevant information.
Compression also incurs a creation cost. Accounting for the writer’s tokens removes its token advantage at the study’s evaluated reuse rate, illustrating why shorter stored text alone is an incomplete efficiency measure.
Retrieval and reliability remain obstacles
A chunk-based dense retriever recovers, on average, 40% of a question’s screen-defined answer-bearing memories in its top ten results, compared with about 1% by chance. That is substantially above chance, but still misses most of this screened set. It does not measure recovery of every useful memory or the accuracy of a complete retrieval system.
The headline contrast stays positive in a new session with randomized memory position and under a second reader, gemma-4-31B-it. Individual labels are less stable: changing position alters 10% of pair-level labels in the follow-up run. Without a length-matched irrelevant-memory placebo, the study cannot isolate every effect of inserting extra context.
The scope is also narrow. The tested SciCode and SWE-bench Verified experiments show no measurable benefit even from raw memories. The factual-recall results therefore do not establish improvements for coding or acting agents.
The authors release a versioned dataset of 16,816 records, although it does not cover every later analysis. Their practical recommendation is to judge memory compression by the task utility it preserves alongside its costs—and to check whether those measurements remain stable.
- AI agent memory
- long-term memory
- task-conditioned utility
- memory compression
- factual recall
- LongMemEval-V2
- retrieval
- counterfactual evaluation