TRANSMISSION // 2611.03705v1
A Formula-Aware Map Helps AI Navigate Spreadsheets with Less Data
Source published
Tie Cheng’s preprint describes a compact spreadsheet representation that preserves table structure and repeated formula patterns. In a 50-case evaluation using GPT-4.1, the approach answered some queries without detailed cell contents and reduced data requests and token use when further information was needed.
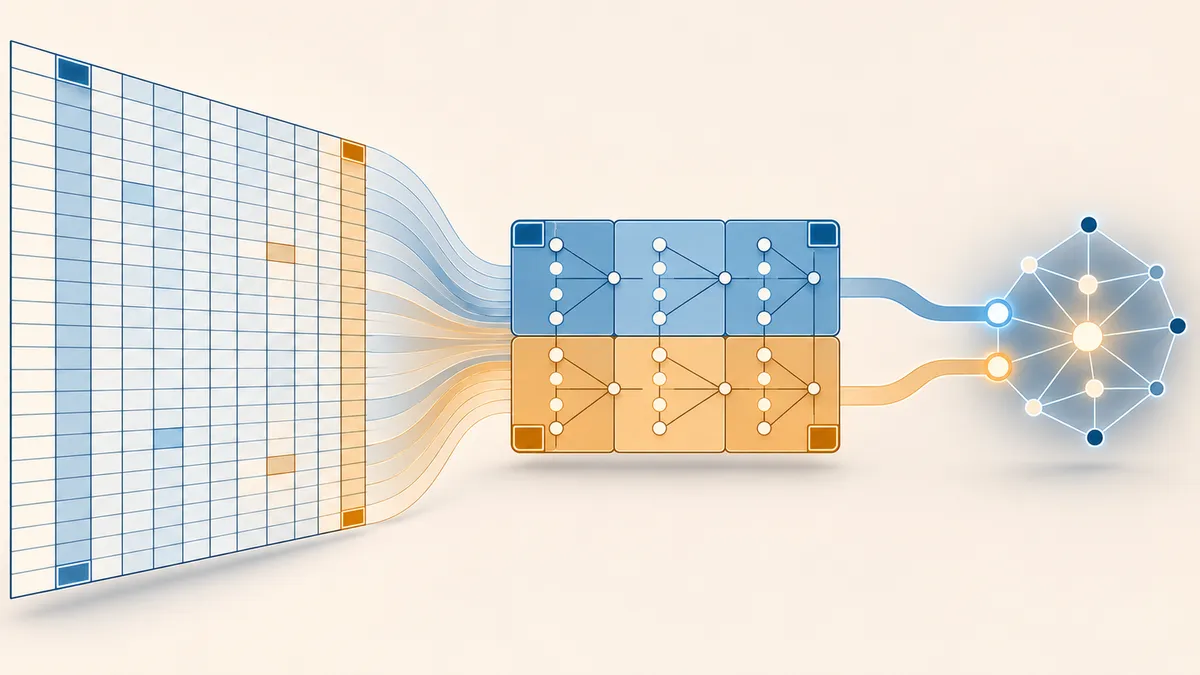
An AI assistant asked to write a spreadsheet formula may need to understand the columns, not read every transaction. A preprint by Tie Cheng explores how to make that distinction explicit: give the model a structured map of the worksheet first, then supply detailed values and formulas only where needed.
Spreadsheet formulas contain information that a plain list of values can leave out. A calculated column, for example, reveals a repeated relationship between other columns. In A Compact Formula-Aware Spreadsheet Abstraction for Large Language Models, Tie Cheng proposes using those relationships to build a smaller, more informative representation for an AI assistant. The work is available as an arXiv preprint; the supplied manuscript also appears in the EuSpRIG 2026 conference proceedings.
The approach does not replace a spreadsheet with a complete copy in another format. Instead, it summarizes regular regions through their locations, data types, repeated formula patterns and selected boundary values. Individual cells outside those regions remain explicitly represented. The model receives this structural overview alongside the user’s question and identifies whether it needs additional spreadsheet content.
Keeping repeated calculations visible
The method groups cells that share a data type and, where applicable, the same formula expressed in R1C1 notation. Unlike familiar references such as C2, this notation can describe a reference relative to the formula’s own position. Formulas copied down a column can therefore share one pattern even though their row numbers differ.
The detection algorithm begins with large vertical lists containing repeated formula patterns. It follows their references to identify further lists, then looks for additional columns with consistent data types. Neighboring lists with compatible heights and positions are grouped into tables, with some tolerance for empty cells. The algorithm subsequently separates headers from data and serializes the resulting structure as text.
Headers retain their actual values rather than being reduced to types. This matters because a label such as “Quantity” tells the model more than the fact that the cells below it contain numbers. Repeated formulas likewise remain part of the summary, rather than disappearing behind their calculated results.
A formula request is not a request for every value
The paper illustrates the distinction with a sales table occupying A1:E910. Its columns describe products, dates, unit prices, quantities and total prices. The user asks for a formula that will list unique products whose combined quantity exceeds 10.
In Cheng’s example, the abstraction provides enough information to generate that formula without transmitting every sales record. Asking for the actual qualifying product list is different: the model needs the product and quantity values. With the abstraction, it requests those columns rather than the entire five-column table.
The workflow still involves a subsequent model request to obtain the final answer. “Abstraction alone” means no additional detailed cell contents are needed, not that the system necessarily answers in a single model call.
What the evaluation found
Cheng compared the abstraction approach in AI Agent for Excel with the baseline implementation in AI-aided Formula Editor. Both used the same GPT-4.1 version, gpt-4.1-2025-04-14. The 50 spreadsheet-query cases came from the developer’s case database and consenting pilot users, with worksheets ranging from 100 to 10,000 cells.
In a single-run evaluation, 12 cases could be answered correctly without any spreadsheet content. Of the remaining 38, the abstraction supplied enough information to answer 11 correctly without requesting further detailed contents.
For the other 27 cases, which required additional data, Cheng reports a 77% reduction in the volume of requested cells and an 86% reduction in total token consumption compared with the baseline. The token measurement covered the complete interaction, including range identification and the subsequent answer request. These are reported results for that evaluated group, not guaranteed savings for every spreadsheet.
A separate reliability assessment ran each case three times under each approach and manually judged final-answer correctness. The baseline failed at least once in 22 cases. Within that subset, the abstraction approach produced correct answers on all three runs in 16 cases. Three successful runs demonstrate the observed outcome, not a guarantee of future correctness.
Where the representation remains incomplete
The evaluation covers one model version and a 50-case collection. The paper also identifies structural limitations. Its algorithm focuses on vertical lists; an analogous procedure for horizontal lists is proposed as future work. Numerous scattered cells can still require substantial token use because they are transmitted individually.
Merged cells are not explicitly handled and can disrupt header detection. Formatting cues, including bold text, colors and borders, are not systematically exploited either. Cheng proposes extending the representation and combining AI with deterministic spreadsheet analyses. Those possibilities remain distinct from the demonstrated result: a formula-aware overview helped this evaluated system request less data and answer more consistently in the reported cases.
- spreadsheet abstraction
- large language models
- spreadsheet formulas
- R1C1 notation
- table detection
- token efficiency
- GPT-4.1