TRANSMISSION // 2611.03674v1
ReVi plans the story before generating a novel’s video recap
Source published
The ReVi preprint describes a multi-agent system that turns novels into narrated video recaps under a viewing-time budget. Its reported experiments combine higher story-quality scores with better duration compliance than the tested baselines, while a separate policy-search experiment examines improvements to both editing instructions and the procedure used to revise them.
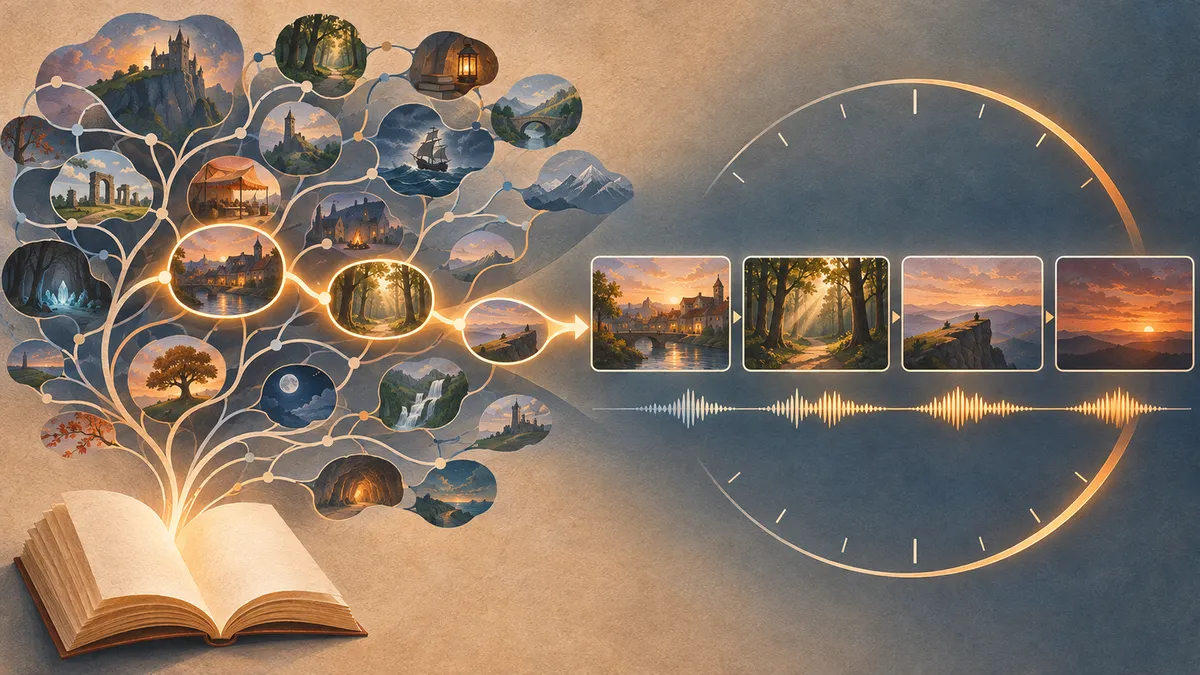
A short recap needs more than a shortened plot: viewers still need to understand why events happen, and the pictures must match the narration. ReVi tackles these connected problems by selecting events, measuring spoken narration and planning shots before generating footage.
Turning a novel into a three-minute video means deciding not just what to leave out, but which explanations must remain. A character’s arrival somewhere may make little sense if the recap drops the invitation, motivation or discovery that prompted the journey. In the preprint ReVi: Recursive Recap Video Generation, Kyrie You Wu and colleagues propose a system that treats these editorial decisions as prerequisites for video generation.
The task differs from both making a full screen adaptation and assembling a recap from existing film clips. ReVi produces narration and newly generated visuals directly from a novel, aiming for a self-contained retelling within a specified runtime. Its guiding principle is “edit first, generate second.”
Selecting, timing and showing the story
ReVi begins with a Story Mapper that represents events and their relationships in a source-linked graph. Events record participants, motivations, actions and outcomes, alongside supporting passages. Connections capture prerequisites, causal dependencies and setups that explain later payoffs. The representation also distinguishes chronological order from the order in which the novel reveals information.
Three editing agents then handle different decisions. The Paper Editor selects, compresses, omits or merges events while checking that retained developments remain understandable. Where necessary, it inserts a concise, source-supported connection across omitted material. Internal motivations can be assigned to narration rather than turned into invented visible actions.
The Radio Editor writes narration and distributes the available time. Some developments receive a brief summary; others get fuller treatment or an explanatory pause. Text-to-speech supplies measured durations rather than relying only on estimated word counts. Persistent overload can send the plan back for deeper story compression.
Finally, the audiovisual planner divides narration into “Dramatic Beats”: changes in actions, goals, outcomes or other event features. It maps these beats to shots and generation requests. Sentence boundaries alone need not define the visual sequence. After generation, checks can trigger repairs at the earliest responsible stage, with dependent outputs recomputed and unaffected material reused.
What the comparisons found
The main evaluation used 15 FilmEval narrative texts, with targets of 90, 120 or 150 seconds depending on difficulty, and 12 held-out novels from the authors’ Recap32 collection, each targeting 180 seconds.
Three Gemini 3.7 Flash judgments assessed each finished video. The reported dimensions were recap fidelity, narrative pacing and audiovisual grounding. Grounding measures whether visuals support or complement narration; it is not an overall average score.
On FilmEval, ReVi scored 91.58 for fidelity, 90.20 for pacing and 88.67 for grounding, on 0–100 scales. ViMax, the primary system-level baseline, scored 82.09, 78.44 and 78.66 respectively. ReVi also led the tested methods on the Recap32 quality measures.
All 15 FilmEval and 12 Recap32 outputs from ReVi finished within the study’s five-percent runtime tolerance. None of the baseline outputs passed that threshold in the main comparison. An important qualification is that baselines received the target duration in their prompts, but their original pipelines did not enforce it.
A separate control gave every method identical human-edited narration and audio for each source. ReVi still outscored ViMax across the three quality dimensions on both collections, providing evidence about downstream visual realization when spoken content and timing were fixed.
Improving the editing instructions
ReVi’s second loop operates across novels rather than repairing just one video. It revises reusable editing policies and a “meta policy” governing diagnosis, proposed changes and search allocation. These policies consist of prompt instructions, examples and configuration rules. Foundation models and evaluation rules remain fixed.
In ten paired searches over five revision rounds, editing-policy revision increased mean quality by 2.26 points over the frozen condition. Allowing meta-policy revision as well increased the gain to 4.47 points. These results concern six Recap32 test novels; their uncertainty intervals describe variation across search runs, not a broader population of novels.
Evidence with defined boundaries
Three human raters assessed 42 videos covering six FilmEval sources and seven methods. ReVi received the highest mean ratings in all three dimensions. The paper nevertheless characterizes human corroboration of automatic fidelity scores as limited, noting the small source sample and partial rater agreement.
The three automatic evaluations per video were repeated judgments, not independent video generations. Reported per-video generation costs also exclude offline policy search. The authors identify broader testing, independent generations and stronger human fidelity assessment as future work. Within those boundaries, the preprint presents evidence that coordinated editing can improve both measured recap quality and adherence to a viewing-time budget.
- ReVi
- novel-to-recap video generation
- multi-agent systems
- narrative compression
- timed narration
- audiovisual alignment
- recursive policy improvement