TRANSMISSION // 2611.00661v2
Lean behavioral profiles improve AI simulations—but not every kind of prediction
Source published
A preprint finds that carefully selected descriptions of earlier behavior help language models reproduce human outcome distributions under new experimental rules. More detailed profiles offer no clear additional benefit, transfer between game types is uneven, and one experiment reveals a crucial gap between matching aggregate patterns and predicting particular choices.
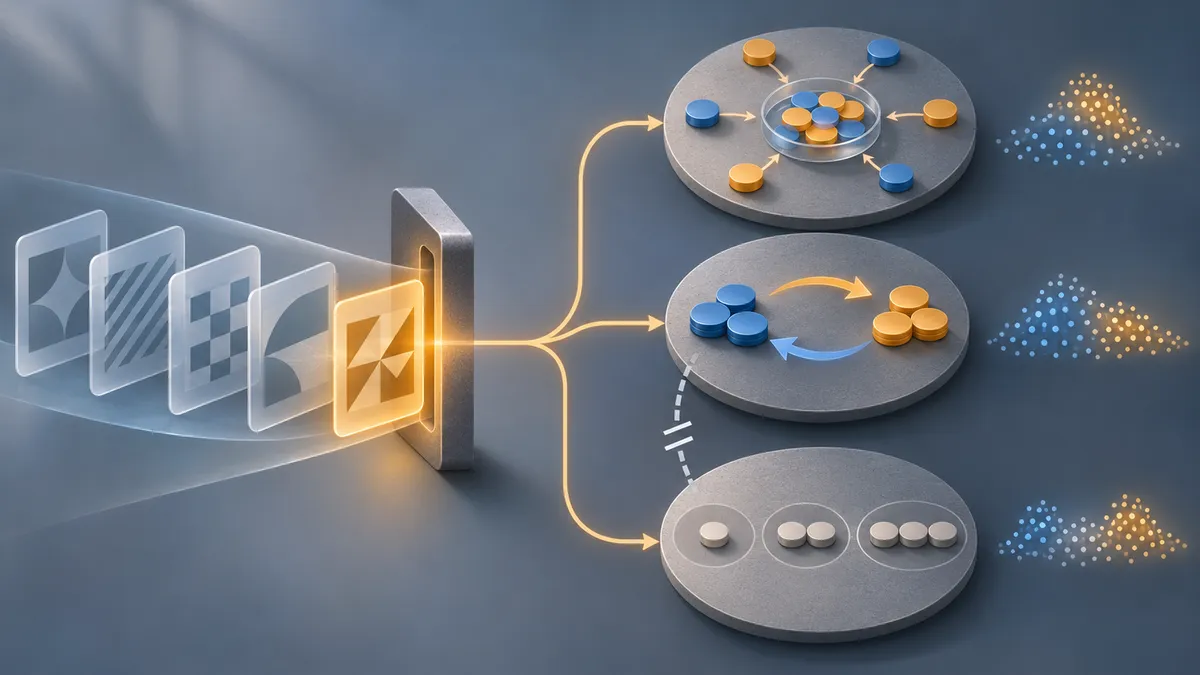
When a language model simulates people, a detailed fictional biography may be less useful than one well-chosen description of observed behavior. A new preprint tests how researchers can select that information—and shows why better-looking population patterns do not necessarily mean better predictions for a specific situation.
Choosing what a simulated person should know
Language models are increasingly used to simulate human decisions, including responses to rules or incentives that researchers have not yet tested on people. But what information should a model receive about the population it represents?
In a preprint, Robin Na, Kehang Zhu, Logan Cross and Michiel A. Bakker treat that question as an experimental design problem. Rather than assuming a richer persona produces a better simulation, they select behavioral descriptions according to whether those descriptions improve predictions in earlier experiments. They then test the selected information with different participants facing new experimental designs.
Their main finding is encouraging but bounded: carefully chosen one-feature profiles improved agreement with human outcome distributions in three families of economic games. Adding more features brought no clear additional benefit. These results concern population patterns, not predictions about particular individuals.
From observed actions to a profile
The researchers began with behavioral features drawn from the relevant literature: 30 candidates for public-goods games, 20 for bargaining and seven for money-request games. They defined scoring rules before examining simulation results.
A profile-generating language model examined earlier actions and, where available, messages and surveys. It assigned scores from zero to ten only when records provided qualifying evidence. Each displayed feature included its score, the model’s certainty and supporting observations. Unsupported features were omitted rather than assigned a neutral value.
A separate simulation stage used sampled profiles to generate behavior. The researchers compared individual features, then added features one at a time while they improved the prescribed learning comparisons. Records supplying profiles were separate from the human outcomes used to evaluate those simulations.
Validation used 250 public-goods games, 48 bargaining games and 884 previously unseen money-request designs. The primary simulator was GPT-5-mini; profile generation used GPT-5-mini or GPT-5.1, depending on the game family.
Three useful descriptions
The leading public-goods feature described withdrawal after adverse peer behavior: how sharply someone reduced contributions following free riding, conflict or another negative social event. These games involve repeated contributions to a shared account, sometimes with communication, rewards or punishment.
For bargaining, the leading feature was package breadth—the tendency to negotiate larger multi-chip exchanges rather than smaller trades. Validation increased the number of chip types from the two or three represented during learning to four.
For generalized 11–20 money-request games, the leading feature was sensitivity to payoffs and incentives. Participants choose a number under rules determining base payments and bonuses. Because almost everyone made only one choice, these profiles represented weighted response types, not established individual personalities.
The researchers compared simulated and human outcome distributions using Wasserstein distance, a measure of distributional mismatch. Their normalized alignment scale places an uninformed reference at zero and the expected agreement between two resampled human datasets at 100. These scores are not percentages of decisions predicted correctly.
Leading one-feature profiles scored 65.5 in public goods, 77.5 in bargaining and 73.5 in money requests. Without profiles, the corresponding scores were −1.0, 40.5 and 12.2. Paired bootstrap comparisons favored the leading profiles over no profile and each of three general-purpose persona libraries.
Two-feature profiles provided no clear validation improvement over one feature. Complete profiles were clearly worse in bargaining; differences in the other two families were inconclusive, not proof of equal performance.
An aggregate success with a warning
The money-request result has an important qualification. Its headline measure pooled requests across different payoff designs sharing a bonus rule. A simulation could therefore match the overall mix of requests while assigning them to the wrong designs.
Two secondary comparisons evaluated predictions within individual payoff designs. Both favored simulations without profiles. No uncertainty intervals were reported for those comparisons, and neither estimated a full simulated choice distribution within each design.
The aggregate improvement therefore does not establish better predictions of responses to a particular payoff change.
Transfer has boundaries
Profiles also traveled unevenly between game families. Public-goods and bargaining profiles improved aggregate money-request alignment. In the reverse direction, the leading money-request profile pushed public-goods alignment to −68.0, clearly worse than no profile. Adding information did not reliably repair transfer.
The authors also caution that most inferred features lack independent psychological measurements or human-coded benchmarks. Evidence checks do not establish that a score measures a stable trait, and predictive success does not establish a causal mechanism.
General-purpose personas represented different populations, so their comparison cannot isolate the effects of profile content. Selected features changed with the models, forward selection could miss useful combinations, and demographic biases were not evaluated.
The practical lesson is to test behavioral descriptions against the outcome and setting that matter—not assume that greater detail, or success elsewhere, makes a simulation trustworthy.
- large language models
- behavioral simulation
- behavioral profiles
- experimental economics
- out-of-distribution generalization
- feature selection
- public-goods games
- multi-party bargaining
- population-level prediction