TRANSMISSION // 2610.40309v2
A More Targeted Way to Make Vision–Language AI Resist Image Attacks
Source published
Adversarial fine-tuning can make vision–language models harder to fool, but may weaken their ability to recognize new categories without task-specific training. A new method, TRAG, uses local responses from a model’s text encoder to guide which changes to its visual representations should be constrained. The paper reports improved clean and adversarial performance across several tested tasks and architectures. These are preprint results, and the evidence does not establish how well the method will work beyond the tested settings.
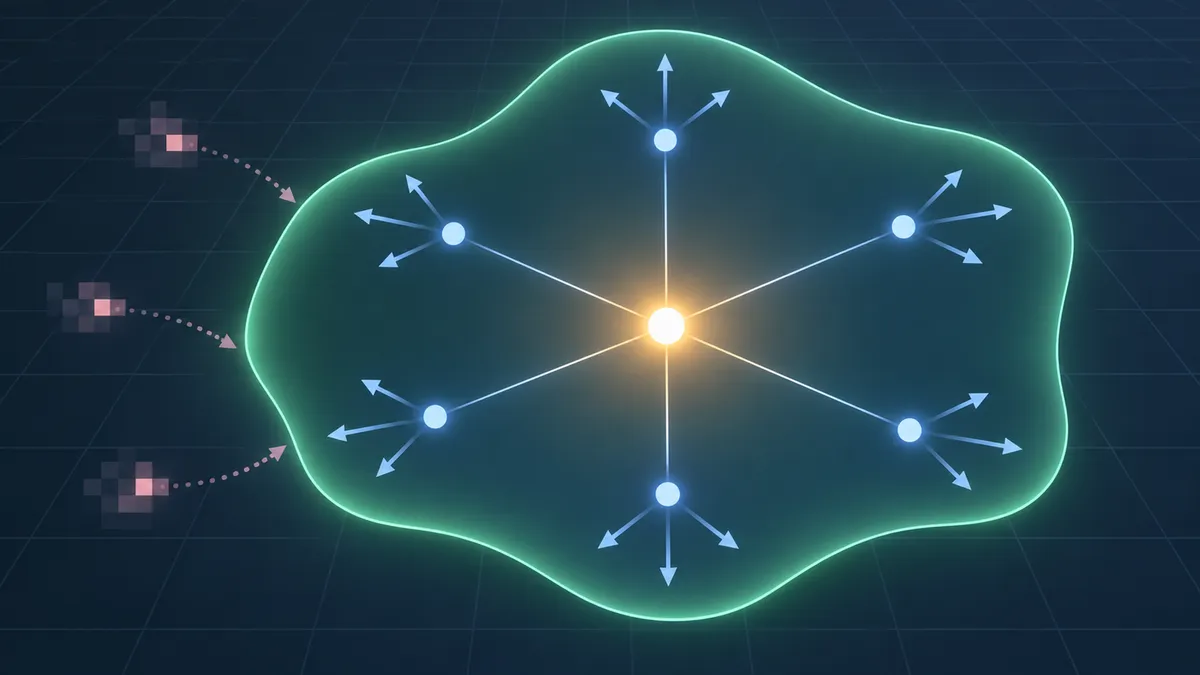
Vision–language models can match images with words they were not specifically trained to classify. But small, carefully chosen changes to an image can disrupt their predictions. Can fine-tuning make these systems more resistant to such attacks without sacrificing their ability to generalize? A new preprint proposes a way to guide that trade-off.
Vision–language models learn to connect images and text in a shared mathematical space. That connection lets a model such as CLIP compare an image with candidate descriptions, including categories not used in a task-specific training step. This flexibility is called zero-shot generalization. It has a vulnerability: small, deliberately designed changes to an image can alter a model’s prediction. Fine-tuning on adversarial examples can improve resistance, but may also disturb the image–text relationships that support zero-shot use.
Yubo Cui, Xianchao Guan and Zheng Zhang propose a method called Textual Response-Aware Guidance, or TRAG, for this problem. Their paper asks whether guidance during adversarial fine-tuning can protect useful image–text relationships more selectively than existing approaches.
Why the direction of change matters
The authors examine two ways earlier methods try to keep a fine-tuned model close to its pretrained version. Feature matching penalizes changes to visual representations broadly, treating directions in the representation space alike. This offers wide coverage, the authors argue, but does not emphasize directions that matter more for meaning. Prediction-distribution matching instead compares the model’s probabilities over a set of candidate texts. That can emphasize semantically relevant differences, but depends on which texts are included and how their probabilities are distributed.
TRAG is designed to combine broader coverage with semantic emphasis. It uses the pretrained model’s text encoder to examine how text representations respond to small changes in their input embeddings. The researchers treat these local responses as directional clues to possible semantic variations around selected text anchors. They then weight the resulting constraints according to how relevant each anchor is to a clean image. During adversarial fine-tuning, the method penalizes visual-representation drift according to this image-specific combination of constraints.
In simpler terms, rather than insisting that the visual representation never move, TRAG aims to discourage movement in directions that could disrupt relevant image–text relationships. The paper applies this guidance while updating the image encoder; the text encoder remains fixed.
What the experiments report
The researchers test TRAG in several settings. For zero-shot classification, they fine-tune CLIP on ImageNet and evaluate it across 16 datasets, using adversarial attacks during evaluation as well as clean images. In the reported main experiment, TRAG’s mean clean and robust accuracy exceed those of the compared fine-tuned baselines. The paper reports gains of 2.5 percentage points in clean accuracy and 1.5 points in robust accuracy over the strongest respective baselines. It also tests other image-encoder architectures and different perturbation budgets, reporting that TRAG leads the compared methods on the mean measures in those experiments.
For image–text retrieval, the authors fine-tune three vision–language models on image–caption pairs and evaluate retrieval on Flickr30k and COCO. They report that TRAG outperforms the fine-tuned baselines on clean and adversarial retrieval measures in those tests. Additional experiments examine text-only and multimodal attacks, and whether robustness transfers when a fine-tuned image encoder is placed in the larger vision–language model LLaVA-1.5-7B. In the latter evaluation, TRAG leads in seven of eight task-and-attack combinations, according to the paper.
The authors also compare how methods preserve the pretrained model’s image–text relationships. Their measures suggest TRAG better preserves some relationships under attack than the tested alternatives, even though it does not always keep visual features closest to their original values. This supports the paper’s central argument: preserving useful relationships is not identical to minimizing every change in representation.
What remains uncertain
These findings come from particular models, datasets, fine-tuning setups and attack protocols. The results do not show that TRAG defeats every possible attack, or that its improvements will carry over to all vision–language systems and real-world uses. The paper’s reported performance is based on benchmark evaluations; it is not evidence of improved safety in every deployment context. Nor does the abstract or provided paper text establish how results would change under substantially different anchor choices, training data or threat models beyond those tested.
The source is an arXiv preprint, not a peer-reviewed journal article in the evidence provided here. Its claims should therefore be read as the authors’ reported results, subject to independent scrutiny and replication. The work offers a specific, technically motivated approach to balancing robustness with zero-shot capability—but further evaluation is needed to establish how broadly that balance holds.
- vision–language models
- adversarial robustness
- zero-shot learning
- TRAG
- machine learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
STAR Gives Task-Relevant Image Pixels Stronger Protection
Source published
Shared keywords: vision language models
Prototype classifiers gain attack resistance from smoother image embeddings—but not guarantees
Source published
Shared keywords: adversarial robustness
How normalization can hide extreme sensitivity in deep neural networks
Source published
Shared keywords: adversarial robustness
When “Hyperbolic” AI Geometry Behaves Almost Euclidean
Source published
Shared keywords: machine learning, vision language models
PhysMoE gives robot vision-language models a more direct way to point
Source published
Shared keywords: machine learning, vision language models