TRANSMISSION // 2610.36991v4
SpectRAG Connects the Dots Before an AI Writes an Answer
Source published
A new retrieval system treats document passages not as isolated search results but as parts of a connected graph. In benchmark tests, SpectRAG recovered more supporting evidence at deeper ranks than several baselines, but gains in answer accuracy were modest, and performance varied by task and domain. The study is a preprint, so its findings need further independent testing.
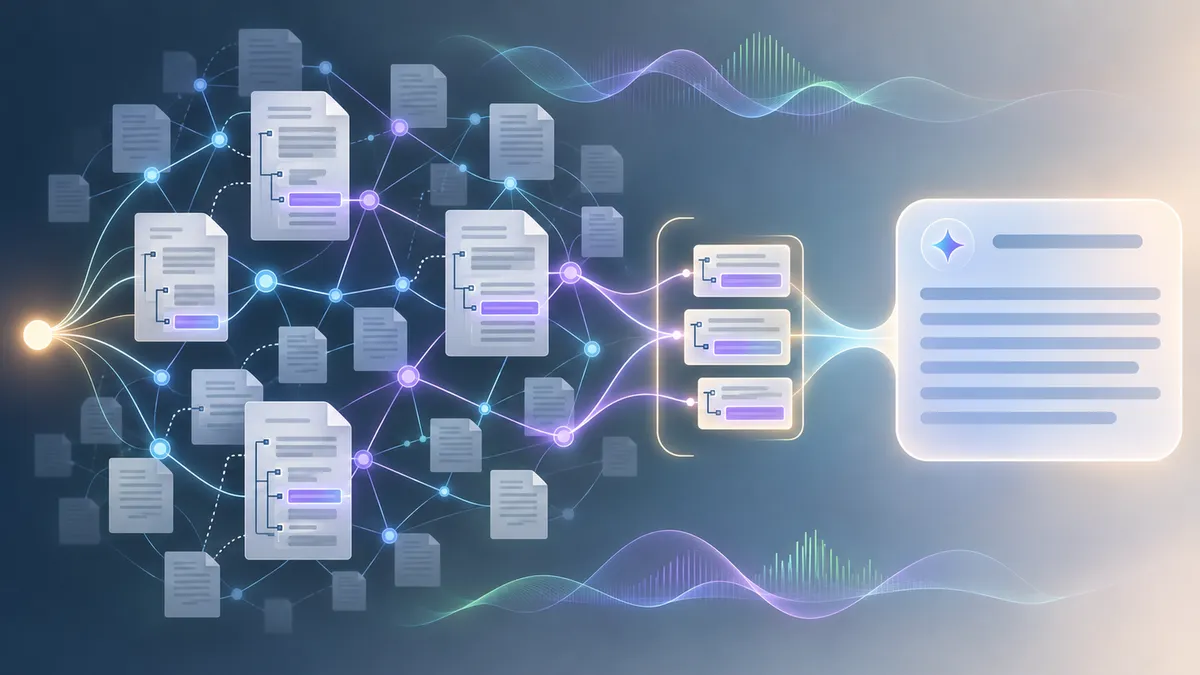
When an AI answers a question that depends on several documents, finding one relevant passage may not be enough. SpectRAG aims to assemble a compact set of connected evidence—without spending the language model’s limited context window on repetition. Its early benchmark results suggest that this strategy can broaden evidence retrieval, though it does not reliably make every answer better.
Retrieval-augmented generation, or RAG, gives a language model passages from an external collection to use while answering. A common approach ranks passages by how closely each one matches the question, then sends the top results to the model. That can work well for a direct lookup. But a question requiring several steps may depend on a chain of facts spread across passages: the passage that supplies a crucial link might not resemble the question closely enough to rank near the top.
SpectRAG, introduced in a preprint, asks whether retrieval should choose a useful set of passages rather than simply rank passages one by one. The system represents document chunks as nodes in a weighted graph. Connections between chunks can reflect semantic similarity, neighboring position in a document, shared section structure or entities, citations, and similarity between questions that a language model generates about each chunk. In this graph, a passage can matter because it connects other relevant passages, even if it is not itself a close match to the original query.
The method works in stages. It first creates a broad set of candidate passages using dense vector search, keyword-based BM25 search, and matches to generated “utility questions.” It expands the candidates through nearby graph connections, then uses graph structure and spectral information to revise relevance scores. Spectral coordinates are a compact representation of a chunk’s position in the graph’s broader structure. Finally, a selection step aims to fit useful, varied passages into a token budget, limiting redundancy while considering coverage across graph clusters and source documents. The selected context is sent to a language model to produce an answer.
The researchers evaluated SpectRAG on MultiHopRAG, which includes multi-step questions with annotated supporting evidence, and on four UltraDomain subject areas: agriculture, computer science, legal material, and a mixed collection. They compared it with vector, hybrid, hypothetical-document, and graph-based RAG systems. The study reports retrieval measures such as recall and reciprocal rank, answer measures including exact match and token overlap, and pairwise judgments of open-ended answers by a language model.
On MultiHopRAG, SpectRAG recovered more annotated evidence at deeper retrieval cutoffs than the systems compared in the paper. Its recall at ten retrieved items was 84.0%, versus 76.1% for the hybrid baseline and 61.8% for LightRAG. But it did not lead every measure of early ranking: Hybrid had the strongest recall at two and five items and the highest mean reciprocal rank, a measure that rewards finding the first relevant item early. SpectRAG’s pattern is therefore better described as broader evidence recovery than uniformly better ranking.
Those retrieval gains translated into a smaller difference in final answers. With the same generator used across systems, SpectRAG scored 71.2% on exact match, compared with 70.6% for Hybrid and 70.5% for LightRAG. The paper reports stronger performance for SpectRAG on inference questions, but other categories were mixed: LightRAG did better on comparison and temporal questions, while several non-graph systems did better at abstaining on unanswerable questions. Retrieving more material is not always helpful if the extra material encourages a model to answer when it should decline.
For open-ended answers on UltraDomain, a language-model judge generally favored SpectRAG over some baselines, particularly for diversity. Against LightRAG, however, the overall preference was close to even and changed slightly with the graph-signal weighting. The legal domain also favored NaiveRAG in the reported preliminary comparison. These judgments are not the same as human evaluations, and the paper describes a limited sample of 20 questions per domain for that comparison.
There are other important caveats. The authors report a smaller persisted index than LightRAG on MultiHopRAG, but SpectRAG’s graph construction uses language-model-assisted extraction and its spectral calculations also have costs. The experiments do not establish that it will be cheaper or more effective in every deployment. Results can depend on chunk size, graph-edge weights, corpus structure, and the question type; the authors also note that exact vector search and spectral computation may be difficult to scale without approximation.
The paper is an arXiv preprint, not evidence of peer-reviewed consensus. Its reported comparisons are benchmark results under particular settings, not a guarantee of better answers in everyday use. The central idea is narrower and promising: linking passages before selecting them may help a RAG system recover evidence that isolated similarity rankings overlook. Whether that advantage holds across larger collections, other tasks, and independent evaluations remains an open question.
- retrieval-augmented generation
- SpectRAG
- multi-hop question answering
- graph retrieval
- language models
- information retrieval
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Lightfoot builds an AI retrieval graph designed to forget documents cleanly
Source published
Shared keywords: multi hop question answering, retrieval augmented generation
Type-aware graph rankings offer a way to guide AI retrieval
Source published
Shared keywords: graph retrieval, language models
FondueQA tests how AI fills gaps in retrieved evidence
Source published
Shared keywords: multi hop question answering, retrieval augmented generation
An AI memory proposal asks what should matter now—not just what matches
Source published
Shared keywords: retrieval augmented generation
A News-Based AI System for Stock Market Questions
Source published
Shared keywords: retrieval augmented generation