TRANSMISSION // 2609.31235v2
Purin gives image classifiers a short-term activity state
Source published
Purin adds a temporary, activity-dependent factor to convolutional neural networks, so recent inputs can influence later responses. In tests on three network architectures and four image datasets, Purin models scored higher than comparison models matched for several design choices. The evidence is limited to these experiments, and the paper is a preprint.
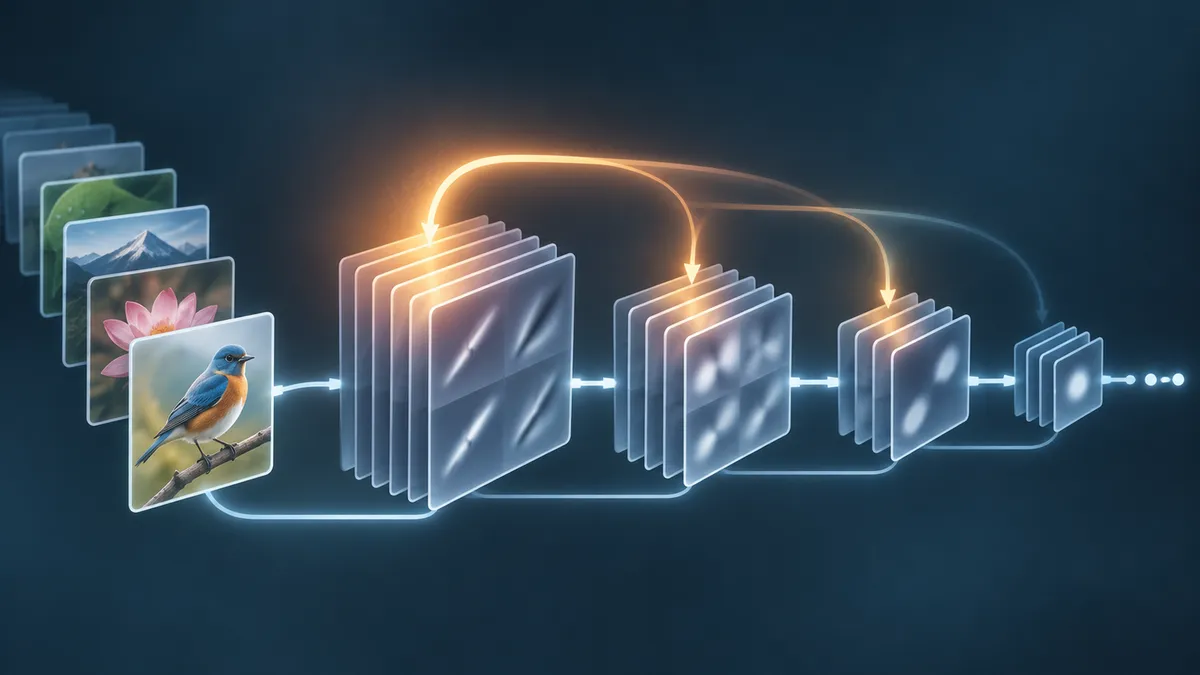
Many image classifiers use learned weights that stay fixed while a batch of examples is processed. Purin adds a temporary factor that changes with recent activity, allowing the same image to produce slightly different outputs depending on what came before. The authors report higher classification accuracy in their matched comparisons, but the results do not establish that the method will help beyond the tested models and datasets.
A network influenced by recent activity
An image classifier passes an image through layers of computation, using learned weights to produce a prediction. During training, those weights are updated; within a batch, they are generally held fixed. Purin adds a temporary, history-dependent modulation to convolutional neural networks (CNNs), a family of models commonly used for image tasks.
The authors draw inspiration from synaptic efficacy: how effectively signals pass between biological neurons. They do not present Purin as a biologically faithful simulation. Rather, it is a simplified way to introduce changing signal strength into networks that use continuous activations and standard backpropagation.
How Purin works
Purin separates a layer’s learned transformation into input-side and output-side weights. These trainable components are updated through backpropagation. A separate temporary factor changes in response to activity as inputs are processed and scales outputs; the factor is bounded between 0.8 and 1.2. In the tested models, however, both this factor and the output-side weights are disabled in the final fully connected layer.
The method treats each still image as information presented over an abstract time interval, without assigning that interval a physical duration. Within a batch, the temporary factor changes and gradually recovers toward its default value. In the main experimental setup, it is reset after each batch and before evaluation stages. The learned weights update through the usual training process. Purin therefore adds this temporary state without converting images into spikes or simulating discrete time steps.
The researchers also tested whether input order affected responses. They froze the learned weights, presented the same images in different orders, and then measured the output for the same target image. For this special test, they did not reset the temporary factor during inference. With the factor enabled, the target’s class scores differed slightly between input orders; with it disabled, the outputs were identical. This demonstrates order-dependent responses in that setup, not a benefit for every task.
What the classification tests found
The experiments used AlexNet, VGG11 and GoogLeNet on four image datasets: CIFAR-100, the aerial-image datasets AID and UCM, and Oxford102, a flower-image dataset. Reported accuracy comparisons were averages over five independent experiments.
A direct comparison with standard versions of the networks would mix Purin’s effects with other design changes. Purin models used different image scaling and activation functions and omitted batch normalization and dropout. The authors therefore also tested “matched” models that shared these choices. In those comparisons, Purin-equipped models had higher reported classification accuracy across all four datasets and all three architectures.
An ablation study compared versions with split weights alone against versions with both split weights and the temporary factor. The authors report that split weights contributed most to the accuracy improvement, while adding the temporary factor often provided a further, smaller gain. This is not a formal numerical division of the improvement into separate causes. The paper also reports small increases in model size and inference computation for the tested configurations; those estimates may not carry over to other architectures.
Limits and open questions
The evidence concerns image classification using three CNN architectures and four datasets. The paper does not test Purin with residual architectures such as ResNet, or establish its performance on other tasks and model families. Because the factor resets between batches in the main setup, these experiments also do not demonstrate persistent memory across a long sequence of batches.
Matched comparisons account for several differences between Purin and standard models, but the results remain limited to the reported experimental settings. The study does not establish how robust the accuracy gains would be under other training conditions, data splits or independent implementations. Nor does an order-dependent response show that Purin reproduces biological synaptic plasticity in detail.
The paper is labeled a preprint submitted to Elsevier, so its findings should be treated as preliminary rather than as a peer-reviewed conclusion. The authors’ results support a narrower claim: in the tested configurations, Purin’s added mechanism coincided with higher accuracy than matched models. Whether that pattern holds more broadly remains to be tested.
- artificial neural networks
- synaptic plasticity
- convolutional neural networks
- image classification
- biology-inspired AI
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Two ways to identify radio signals work better together in a synthetic benchmark
Source published
Shared keywords: convolutional neural networks
Better AI training may start with where the data came from
Source published
Shared keywords: image classification
Prototype classifiers gain attack resistance from smoother image embeddings—but not guarantees
Source published
Shared keywords: image classification
ACTOR uses delayed labels to improve later image classifications
Source published
Shared keywords: image classification
PLUS adds a class-specific signal to help AI spot unfamiliar images
Source published
Shared keywords: image classification