TRANSMISSION // 2609.19589v2
When AI Data Attribution Follows Format, Not Task
Source published
A study finds that gradient-based data attribution for language-model fine-tuning aligns more with answer format than task. The result challenges a common interpretation of these scores, while leaving open how broadly it applies.
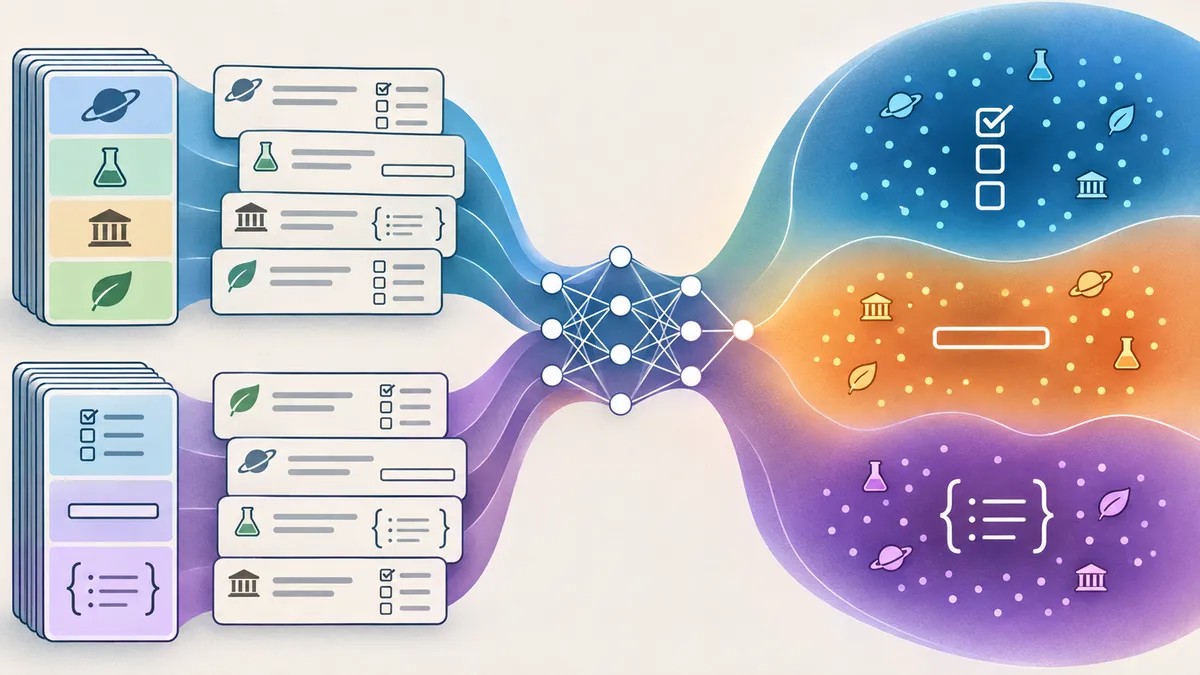
When a language model’s training examples receive similar attribution scores, does that mean they teach the same skill—or simply ask for answers in the same style? A study of supervised fine-tuning finds that answer format is a stronger guide to gradient similarity than task identity in the settings tested.
What do gradient similarities tell us?
Researchers use gradient-based data attribution to estimate which training examples are related to a model’s response to a target task. In simplified terms, the method compares the gradients each example produces: if two gradients point in similar directions, the examples may be treated as related or influential. Some researchers interpret this similarity as evidence that examples share useful skills or task content. Others have argued that similarities in surface form—such as answer length or format—may matter more.
The difficulty is that task and format often come bundled together. A benchmark about science might use multiple-choice answers, while a different benchmark uses short text. If examples align, it is hard to tell whether the connection comes from the subject matter or the way answers are written.
In this preprint, Sunwoo Kim and colleagues try to separate those explanations. Their central question is whether gradient alignment tracks the task being solved or the answer format required.
A controlled comparison
The authors took five English-language benchmarks—TriviaQA, SQuAD, GSM8K, ARC-Challenge and CRUXEval—and rendered their questions in seven answer formats. These included true/false or yes/no, several kinds of four-option choices, and JSON. This produced 35 benchmark-and-format combinations. Because a benchmark could be shown in multiple formats, the researchers could compare different tasks using the same format, or the same task using different formats.
For each combination, they calculated gradients for 64 examples. They compared those gradients using cosine similarity, a measure of how closely two vectors point in the same direction. To account for differences in how consistently examples within each dataset aligned with one another, they adjusted the comparisons using each dataset’s internal coherence. The authors call the resulting measure disattenuated cosine.
They repeated their comparisons across model checkpoints and training stages, including pretraining and post-training, and across model sizes and families. They also examined released data selections from LESS, a gradient-based method for choosing examples for instruction tuning. For three target benchmarks, they compared the answer formats in the selected examples with the formats available in the candidate pool.
Format mattered more in these tests
The clearest pattern was that examples sharing an answer-structure class aligned more strongly, even when they came from different benchmarks. Their reported disattenuated cosine was near 0.4. By contrast, examples from the same benchmark but rendered in different answer-format classes showed alignment near zero. In other words, within this experimental setup, format similarity predicted gradient alignment better than shared benchmark identity.
The authors report that this ordering appeared across the tested models and training stages, from early pretraining checkpoints through post-training. In the LESS selections, each target’s examples were enriched for its own answer format: letter-style choices for MMLU, chain-of-thought answers for BBH, and short answers for TydiQA. The reported enrichment was 3.7-fold, 2.4-fold and 1.9-fold, respectively, relative to each format’s share in the candidate pool.
These results challenge a strong semantic reading of gradient similarity. A high score may indicate that examples resemble one another in the structure of their answers, not necessarily that they teach the same underlying skill. That distinction matters if researchers use attribution scores to select examples specifically because they believe those examples share a target capability.
What the study does—and does not—show
The findings do not establish that format-based selection is useless. The authors explicitly distinguish questioning the interpretation of attribution scores from questioning whether selections can improve benchmark performance. Format-matched examples may genuinely help in targeted instruction tuning, even if their gradients do not primarily encode shared task semantics.
The scope is also limited. The controlled comparisons cover five English question-answering benchmarks and seven formats grouped into three structure classes; JSON is the only structured-generation format. The format classes are choices made by the researchers, not a definitive taxonomy. Gradient comparisons use 64 examples per dataset, and the LESS analysis covers released selections for three targets. Its format labels came from a rule-based classifier that agreed with manual labels on 90% of a held-out sample, so some examples may have been categorized incorrectly.
The paper’s broader recommendation is to test attribution and selection methods on data where task and answer format vary independently. It also identifies further questions, including whether standardizing answer formats would make selections more content-driven and how that might affect fine-tuning. Those are proposed directions, not findings established by this study.
This work is available as an arXiv preprint and is listed as a workshop paper for the NeurIPS 2026 Data Attribution and Provenance workshop. A preprint is a research report that may not have undergone the same review process as a journal or conference proceedings paper. The results offer a controlled warning about how to interpret gradient similarity, but further research is needed to test how well the conclusion extends beyond the benchmarks and settings examined.
Source: Kim et al., “Form Over Content In Gradient-Based Data Attribution Methods,” arXiv:2609.19589v2.
- large language models
- data attribution
- gradient similarity
- instruction tuning
- answer format
- training data selection
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Choosing Less-Repetitive Examples for AI Fine-Tuning
Shared method: Both studies use gradient-based similarity: Kim et al. compare per-example loss gradients across supervised fine-tuning datasets, while Zhao et al. build a gradient-similarity graph for targeted selection. Their aims differ—measuring what gradient alignment reflects versus selecting relevant, diverse examples—and the excerpts do not show that QSGS tested the answer-format confound identified by Kim et al.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2609.19589v2 — Original paper
Excerpt reference:
static/papers/2609.19589v2.md:268-356
Basis: Paper text
Source SHA-256:0e44901481d617dd8995cbb7d40b3a7a5e7924578f643e5e68b336718b2a31282611.04059v1 — Original paper
Excerpt reference:
static/papers/2611.04059v1.md:69-131
Basis: Paper text
Source SHA-256:c7b677ada02ab46f0d9d3d1b9ebfc225b193d43f8558669034a71824cb8b9760
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Choosing Less-Repetitive Examples for AI Fine-Tuning
Source published
Shared keywords: gradient similarity, instruction tuning, large language models
WoW maps educational training data—and shows where its gains stop
Source published
Shared keywords: instruction tuning, large language models
Which data modality matters—and for which example?
Source published
Shared keywords: data attribution
Language models can exaggerate psychological patterns—and internal probes offer only part of the explanation
Source published
Shared keywords: instruction tuning, large language models
When one AI plans and another writes the code
Source published
Shared keywords: instruction tuning, large language models