TRANSMISSION // 2609.19093v2
Why report style can shift chest X-ray AI rankings
Source published
A preprint finds that changing the style of reference reports can change how chest X-ray report-generation models rank on an evaluation metric.
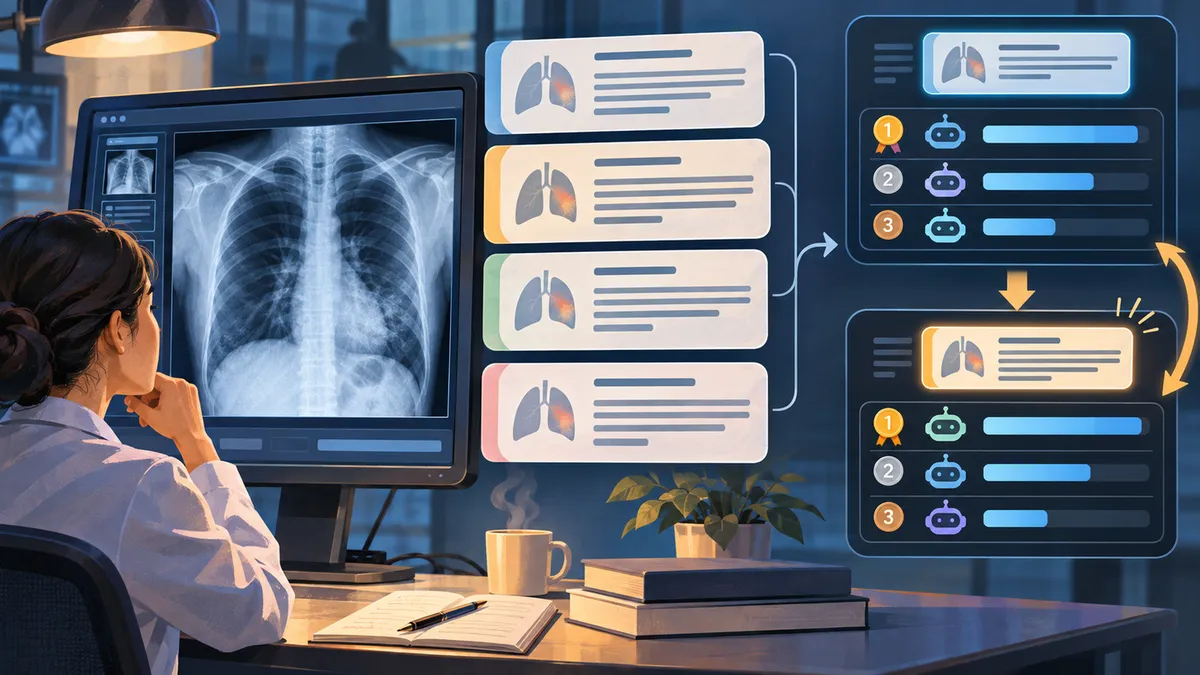
How should we judge an AI-generated chest X-ray report? One common approach compares it with a radiologist’s report. But radiologists can describe the same clinical findings in different ways, and those differences may affect a model’s score.
The reference report is part of the test
AI systems that generate radiology reports are often assessed by comparing their output with a human-written reference. Yet reports can vary in terminology, shorthand, formatting and detail while preserving the same clinical interpretation. A model’s score may therefore reflect both its account of the findings and how closely its wording matches the reference’s reporting style.
In this arXiv preprint, Daniel P. Jeong and colleagues study how variations in reporting practice affect established evaluation metrics for chest X-ray report generation. They introduce a radiologist-informed taxonomy of reporting variations and a method called ReRef, which rewrites reference reports along those dimensions while aiming to preserve clinical interpretation.
A changed reference, a changed ranking
The abstract describes an evaluation of nine report-generation models on MIMIC-CXR using RadCliQ-v1. In one example, the researchers condensed discussion of normal findings in the reference reports. Libra moved from first to second place, while CheXOne rose from third to first.
This is a change in evaluation ranking after the references were rewritten—not evidence that either model’s clinical ability changed. The authors’ broader conclusion is that some current metrics may not separate agreement in clinical interpretation from conformity to reporting conventions.
The team also reports releasing MIMIC-CXR-Ext-ReRef, a radiologist-validated dataset of 120 original and alternative reference-report pairs derived from MIMIC-CXR. The pairs may help researchers examine how reference choice affects evaluation.
What remains uncertain
The practical implication is that reference choice can matter when evaluating report generators. A score based on one reference may reward a particular way of writing as well as the clinical content. The authors suggest that references should reflect the reporting practices an evaluation intends to assess. The abstract does not establish that every metric or model ranking is similarly sensitive, nor does it show that any model is clinically better or worse.
This account is based on the paper’s abstract, so it does not provide enough detail to assess the taxonomy, rewriting procedure or validation in depth, or to determine how broadly the example applies across metrics and settings. The work is identified as an arXiv preprint; the supplied source does not establish whether it has undergone peer review. Its findings are best understood as a reported research result, not settled evidence about clinical performance.
- radiology AI
- chest X-rays
- report generation
- AI evaluation
- MIMIC-CXR
- reference reports
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
AI checks chest X-rays globally, then inspects regions to explain its reports
Supporting evidence: Both studies show that reference-based scores can be affected by the reference, but through different mechanisms: Jeong et al. report that changing reporting style can alter chest X-ray model rankings, while Huang et al. note that reference reports may be imperfect and that automated metrics penalized observations missing from them. This supports a bounded caution about interpreting reference-based scores, not a claim that the studies used the same evaluation setup or found the same effect.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2609.19093v2 — Original paper
Excerpt reference:
static/papers/2609.19093v2.md:1162-1190
Basis: Paper text
Source SHA-256:a841a48eca672a5de33c464f45c8db0daa08566f1ed37e72573a1fa323d497d52609.19093v2 — Original paper
Excerpt reference:
static/papers/2609.19093v2.md:962-1011
Basis: Paper text
Source SHA-256:a841a48eca672a5de33c464f45c8db0daa08566f1ed37e72573a1fa323d497d52611.14018v1 — Original paper
Excerpt reference:
static/papers/2611.14018v1.md:1259-1305
Basis: Paper text
Source SHA-256:59f05fde63bb9bea6e7afc61f2c1728b848ba5d4cfc5d59e9660b51c444d61bd
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI checks chest X-rays globally, then inspects regions to explain its reports
Source published
Shared keywords: chest x rays, radiology ai, report generation
An AI report can copy the structure and still get the facts wrong
Source published
Shared keywords: ai evaluation, report generation
Can one medical-image detector learn across X-rays and mammograms?
Source published
Shared keywords: ai evaluation, chest x rays
Estimating AI Reliability With Fewer Repeated Trials
Source published
Shared keywords: ai evaluation
An AI can answer correctly and still act outside its authority
Source published
Shared keywords: ai evaluation