TRANSMISSION // 2609.07033v4
Better prediction is not always better causal estimation
Source published
A new preprint proposes choosing IV-LASSO settings for the accuracy of the final causal-effect estimate, rather than first-stage prediction. Simulations show substantial gains in some settings, but not universal superiority.
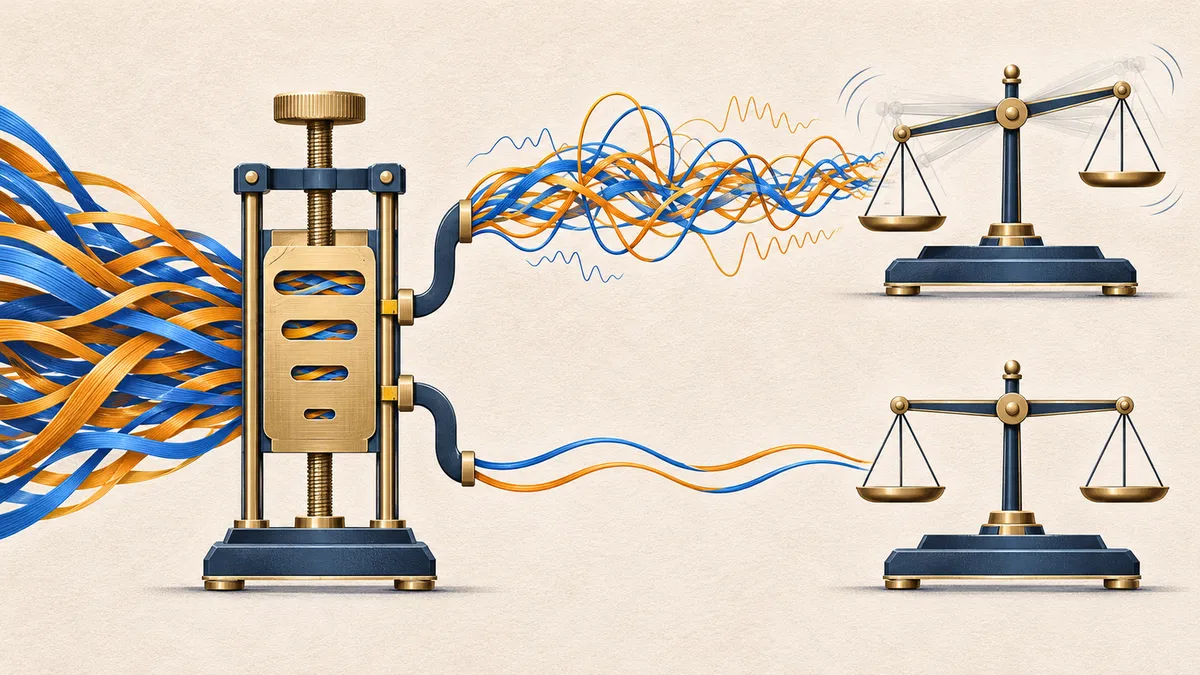
Economists often use machine learning as one step in estimating cause and effect. This paper examines a consequential mismatch: tuning that step to predict well can make the final estimate less accurate.
Two stages, different goals
Suppose researchers want to estimate how credit supply affects exports. Credit growth may be correlated with unobserved influences on exports, making an ordinary regression misleading. Instrumental variables, or IV, methods use outside sources of variation assumed to affect the outcome only through the variable being studied.
The first stage predicts credit growth using those instruments. The resulting fitted values then serve as an instrument for estimating the effect on exports. When researchers have many potential instruments, LASSO can simplify the first stage by shrinking coefficients and setting some to zero.
But LASSO leaves two choices: the dictionary of candidate instruments, including transformations and interactions, and the penalty controlling shrinkage. A richer dictionary or lighter penalty can improve prediction while also capturing noise that contaminates the final effect estimate.
The arXiv preprint Choosing the Dictionary and Penalty for IV-LASSO, whose fourth version was posted on November 9, 2026, proposes tuning these choices for the final estimate rather than prediction alone.
Why endogeneity changes the trade-off
The central issue is endogeneity: correlation between the unexplained part of the variable being studied and the unexplained part of the outcome. When the same observations are used for fitting and estimation, a flexible first stage can absorb noise correlated with the outcome error.
Cross-validation evaluates prediction on held-out observations. It does not directly account for how this error correlation affects the final full-sample IV estimate. The proposed criterion does, assigning a larger complexity cost when endogeneity is stronger.
Complexity is measured through an effective dimension. Usually, this agrees with the number of instruments LASSO selects. When dictionary columns are linearly dependent, it instead counts independent directions, avoiding ambiguity from different coefficient solutions that produce identical predictions.
The theoretical criterion balances approximation of the optimal instrument against a complexity cost involving both the average effective dimension and its variability. It also recognizes that multiplying an instrument by a nonzero constant does not change the IV estimate, so prediction error alone is not the appropriate yardstick.
Making the comparison computable
The ideal criterion contains unknown population quantities. The authors construct a usable score from each candidate’s fitted values, observed effective dimension and estimates of error moments obtained using a preliminary effect estimate.
Their analysis handles LASSO’s changing variable selection rather than assuming that it eventually selects one fixed model. Geometric properties of LASSO and statistical identities relating noise to fitted values make the higher-order calculations possible.
Another obstacle is that estimation error in the score can exceed the small differences between candidates. The authors show that its leading contribution is shared across candidates and therefore cancels when they are compared.
Under their assumptions, the selected dictionary–penalty pair approaches the best candidate’s distinguishing component of approximate mean squared error as the sample grows. This is a guarantee within a fixed, prespecified candidate list—not a search over every possible model.
What the simulations found
The simulations use instruments from a published credit-supply and exports study, holding their observed values fixed while generating new outcomes and credit growth. They use 14,208 export-flow observations, vary instrument strength and endogeneity, and run 1,000 replications per design.
The proposed rule and ordinary cross-validation choose among 74 combinations: two dictionaries and 37 penalty settings for each. Comparisons also include a calibrated plug-in penalty and cross-fitting, which constructs instruments using predictions for observations excluded from each training sample.
At low endogeneity, the proposed rule and cross-validation perform similarly. In selected Gaussian designs, its mean squared error is more than 50% below the plug-in rule’s at the lowest endogeneity levels. At the highest levels, it is 30–50% below ordinary cross-validation’s.
The rule does not win everywhere. Cross-validation performs better in some intermediate-endogeneity settings. Across the main Gaussian designs, the proposed rule’s worst relative risk is about 20% above the best of the four feasible methods.
Where the evidence stops
The main theory assumes one endogenous regressor, strong identification, independent observations and homoskedastic Gaussian errors. It also requires sparsity and a growing core of sufficiently strong first-stage coefficients. It is not a general weak-instrument guarantee.
A supplementary appendix extends the results to a restricted class of non-Gaussian errors. Simulations also show similar performance under shared-scale Laplace errors outside that extension, but those experiments do not establish a broader theorem.
Finally, approximate mean squared error is not exact finite-sample mean squared error, which may not exist for IV estimators. The work remains a preprint and offers a tuning method, not evidence that any application’s instruments are valid. Its practical message is narrower: optimize the intermediate prediction step for the downstream estimation problem it is meant to support.
- instrumental variables
- LASSO
- causal inference
- model selection
- endogeneity
- econometrics
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When Many AI-Generated Controls Can Help Regression—and When They Cannot
Source published
Shared keywords: instrumental variables
When machine learning meets weak instruments, precision can mislead
Source published
Shared keywords: instrumental variables
When an Imperfect Instrument Can Still Help Estimate a Causal Effect
Source published
Shared keywords: causal inference
When clustered data make weak instruments harder to trust
Source published
Shared keywords: instrumental variables
When Dynamic Panel Regressions Misread Treatment Effects
Source published
Shared keywords: causal inference, instrumental variables