TRANSMISSION // 2606.26969v2
Could AI Think by Watching Its Own Imagined Scenes?
Source published
Einstein World Models propose adding short, generated video rollouts to a language model’s reasoning trace. The paper offers an architecture and training plan, not evidence that the approach improves performance: its authors identify suitable training data and evaluation as open needs.
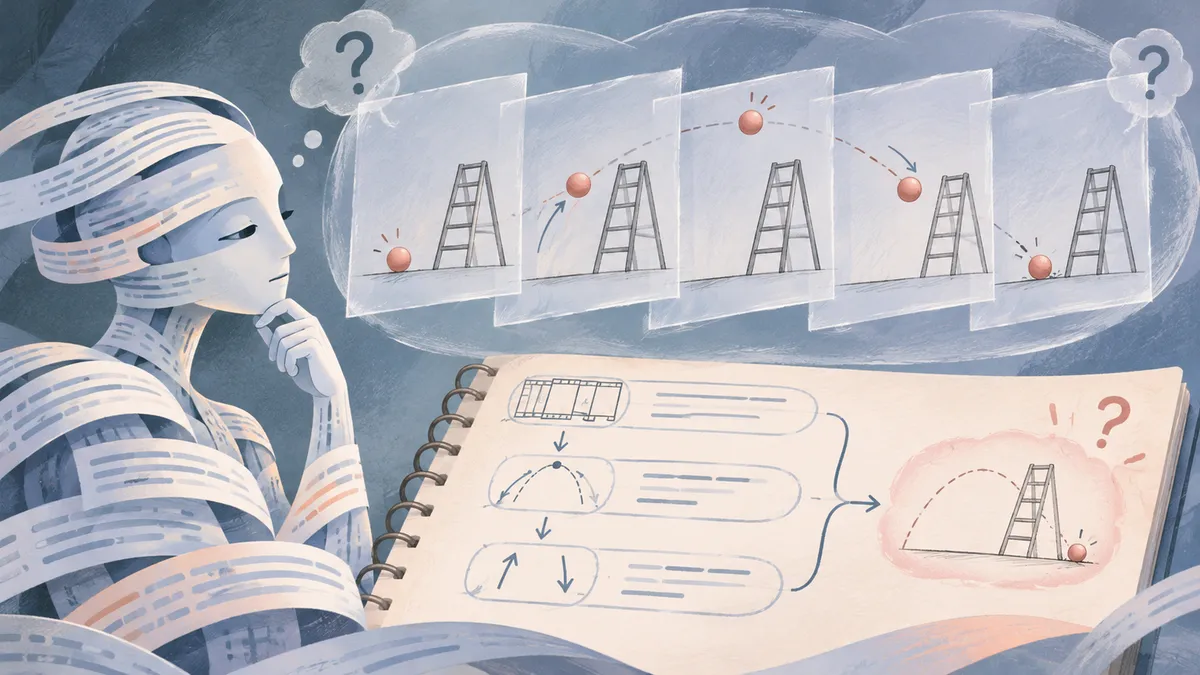
When a question asks what happens over time, words can be an awkward scratchpad. A model might benefit from constructing a little scene, then examining how it unfolds. A preprint called *Einstein World Models* sketches a way to give language models that option—but it is a proposal, not a demonstration that the method works.
A question about two balls thrown into the air is not just about objects and heights. It also asks you to keep track of time: where are the balls after the juggler has climbed a ladder? A person may picture the scene and notice that both balls would fall long before the climb is finished. A language model, by contrast, may get tangled in describing the problem or its missing details.
That gap motivates Einstein World Models, a preprint by Munachiso Samuel Nwadike and colleagues. The paper asks whether visualising a possible event could complement text-based reasoning. Its answer is a proposed design: let a language model call a video-generating component to produce a short rollout—a sequence showing how a described scene might develop—and then use that sequence as an intermediate aid to reasoning.
A visual tool, not an answer machine
The authors distinguish their proposal from a conventional “world model,” which typically predicts how an environment will change, often to help an agent plan actions. In their terminology, an Einstein World Model is the overall reasoning system. The language model remains in charge; it can decide whether to request a visualisation, phrase the request, and continue reasoning after receiving the result.
The generated video is not supposed to settle the question by itself. Instead, it becomes an inspectable hypothesis within the model’s reasoning trace. A person evaluating the system could examine what scene it generated and whether the model used that scene sensibly. The authors stress that visibility is not the same as accuracy: a video can be easy to inspect and still depict events implausibly.
The idea extends familiar AI tool use. A model might search the web for information or run code for a calculation; here, it might request a visual thought experiment when a problem depends on motion, contact, containment, or changes over time. The authors also describe possible training approaches: first teach the model the format for traces that include text and visual rollouts, then use reinforcement learning with answer-checking to encourage useful tool calls. A possible reward could discourage excessive calls. These are recommendations for building a system, not results from a completed training study described in the paper.
What the paper does—and doesn’t—show
The preprint’s main contribution is a blueprint: a proposed reasoning architecture, a distinction between the language-model reasoner and the component generating scenes, and guidance on training and selecting that component. It discusses video renderers and interactive simulators as possible tools, but does not report benchmark results establishing that an Einstein World Model answers questions more accurately than a text-only model.
The authors identify a major obstacle: data. They argue that existing resources often start with an image or video already supplied, whereas their target is a text-only question where the model must decide whether to create a visualisation at all. A useful dataset would include both questions that benefit from visual thought experiments and questions that do not, so the system could learn when to refrain. The paper points to SimpleBench as an illustration of the kind of text-based challenge it has in mind, while noting that its public release is too limited to serve as a training corpus.
There is also a basic reliability concern. Video generators can produce physically inconsistent scenes, and a misleading rollout could distract rather than help. Even a plausible-looking sequence would not prove that the model’s final answer was based on it: as with written reasoning traces, an intermediate artifact might fail to faithfully reveal how an answer was reached. The paper treats rollout quality, faithful use, and evaluation as problems for future work rather than settled properties.
The central claim, then, is modest but interesting: language models might gain a useful reasoning tool by making imagined events visible and examinable. Whether this improves answers, for which tasks, and at what computational cost remains open. The source is an arXiv preprint—a research manuscript, not evidence of peer-reviewed confirmation—and its proposal should be read as a research direction rather than a demonstrated capability.
- artificial intelligence
- large language models
- visual reasoning
- video generation
- AI tools
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI can read an image yet struggle to reason about it
Source published
Shared keywords: visual reasoning
AI can find research papers, but weighing their evidence is harder
Source published
Shared keywords: large language models
When visual AI learns the answer but loses the thread
Source published
Shared keywords: visual reasoning
NextGAN trains a critic to guide faster image and video generation
Source published
Shared keywords: video generation
Teaching Video Generators Which Emotional Cues to Trust
Source published
Shared keywords: video generation