TRANSMISSION // 2605.28063v2
PlanAudio gives text-to-audio generation a sense of sequence
Source published
A drum roll, a crash, then a shouted line: PlanAudio is designed to turn prompts like this into one coordinated recording. The researchers report stronger results than tested alternatives on combined speech-and-sound generation, while finding trade-offs in speech quality and important limits in how broadly the evaluation can support their claims.
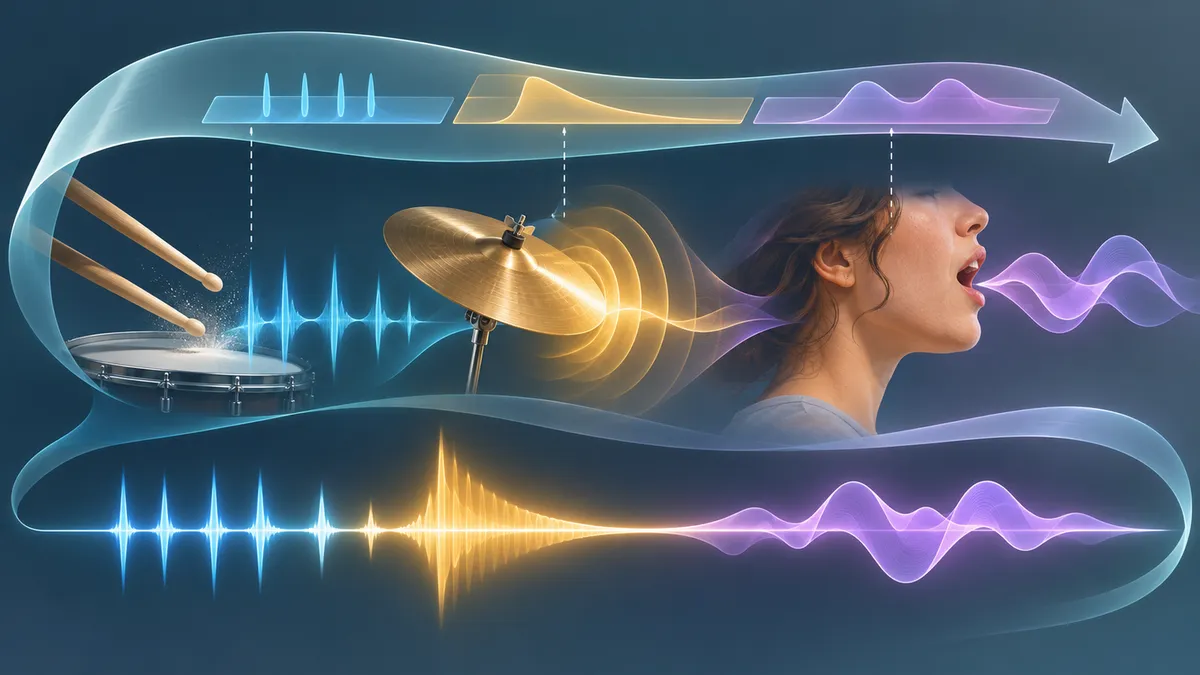
Turning a free-form description into a coherent soundtrack is not just a matter of producing the right sounds. A system must also get their order and interplay right. PlanAudio attempts this with an internal planning step before it generates audio.
Imagine asking an audio generator for a fast drum roll, a cymbal crash, and then someone shouting “Come on!” A system could produce each ingredient yet still get the sequence wrong, make the voice hard to understand, or make the sounds feel like unrelated tracks. This coordination problem is the focus of a paper introducing PlanAudio, a model intended to generate speech, sounds, or both from an ordinary text prompt.
Many existing approaches either combine separate speech and sound generators or ask users—or another model—to reorganize a prompt into structured fields. The authors argue that these extra steps can limit flexible prompting and introduce errors. PlanAudio instead takes the original prompt directly, without a separate text encoder or prompt-rewriting stage.
A plan before the sound
PlanAudio is an autoregressive model: it generates a sequence step by step. Before producing audio tokens, it predicts a short, continuous “audio layout.” This latent plan is meant to represent the broad semantic and temporal organization of the recording—what events belong and how they relate over time. The model then uses both the original prompt and that layout to generate audio tokens, which are decoded into a waveform.
The researchers trained the model on a corpus of 1.43 million clips spanning speech, sound, and combined speech-and-sound. For combined recordings, they used AudioSet clips and generated descriptions by separately transcribing speech and describing the surrounding audio, then joining the information. Each clip was paired with five prompt variations. The paper also introduces FUAG-Bench, an evaluation set whose combined-audio portion contains 4,500 held-out AudioSet clips paired with free-form prompts. Human checks on a sample of those annotations found that the descriptions generally captured the speech, sounds, and event order accurately.
To test performance, the authors compared PlanAudio with unified audio models, specialist speech or sound models, and a pipeline that generated speech and sound separately. Because the alternatives generally required structured inputs for combined audio, they were given prompt splits—sometimes from an automated rewriter and sometimes from the annotations used to construct the data. That makes the comparison relevant to the practical challenge of free-form input, but it also means the systems did not all receive inputs in the same format.
Stronger results on combined audio, with trade-offs
On the combined speech-and-sound test set, PlanAudio performed better than the tested baselines on several sound-related measures. The paper reports closer event timing to the reference and higher semantic coverage: a measure intended to reflect how many events named in the prompt appear in the generated audio. In a listening study, 10 listeners rated 50 examples across four criteria. PlanAudio received the highest average ratings among the compared models for acoustic quality, temporal correctness, semantic alignment, and authenticity.
The results were not uniformly best across every measure. On combined audio, one VoiceLDM variant scored better on speech intelligibility and perceived voice quality. The authors suggest that this may reflect a trade-off: PlanAudio was trained on real recordings where voices are mixed into their acoustic surroundings, while the competing model’s training data included clean speech overlaid on separately recorded sounds. That explanation is the authors’ interpretation, not proof that training-data composition alone caused the difference.
On speech-only and sound-only tests, PlanAudio outperformed the tested unified baseline and was described as competitive with specialist systems. The authors also tested the planning idea directly. Replacing the model’s predicted layout with features taken from the reference audio improved some measures; reversing the layout’s order harmed results. These interventions support the idea that the layout carries useful information about content and sequence. They do not establish that this is the only reason PlanAudio performed well.
What the evidence cannot settle
The study evaluates one PlanAudio checkpoint on the authors’ benchmark, using automated measures and a relatively small listening study. FUAG-Bench is built largely from existing datasets, and the combined-audio prompts are automatically generated, though a sample received human review. Results may differ with other recordings, prompt styles, languages, or evaluation procedures. Several reported metrics are proxies: for example, event-detection systems and similarity scores cannot fully capture whether a recording sounds natural to listeners.
The paper also describes substantial model training and its authors acknowledge the possibility of misuse for deceptive audio generation. Its findings should be read as evidence for a particular system and evaluation setup, not as proof that free-form audio generation is solved. The source is an arXiv preprint associated with NeurIPS 2026; the material provided here does not independently establish peer-review status or validate the reported experiments. The authors say that audio samples are available on the project website, which may help readers judge the examples for themselves.
- audio generation
- speech and sound
- text-to-audio
- autoregressive models
- latent planning
- AI evaluation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AUTEUR tests the gap between text filters and AI-generated sound
Source published
Shared keywords: text to audio
Estimating AI Reliability With Fewer Repeated Trials
Source published
Shared keywords: ai evaluation
An AI can answer correctly and still act outside its authority
Source published
Shared keywords: ai evaluation
Expert Feedback Raises Average Ratings for AI Finance Briefs
Source published
Shared keywords: ai evaluation
Could the shape of word connections help evaluate AI reasoning?
Source published
Shared keywords: ai evaluation