TRANSMISSION // 2605.14786v2
A browser agent’s actions may reveal which AI model is behind it
Source published
A study of 14 language models reports that browser actions and their timing can help identify the model powering an agent. Identification was strongest within a fixed setup and fell to near chance when tested across different setups. The findings are from an arXiv preprint, and the evidence available here is its abstract.
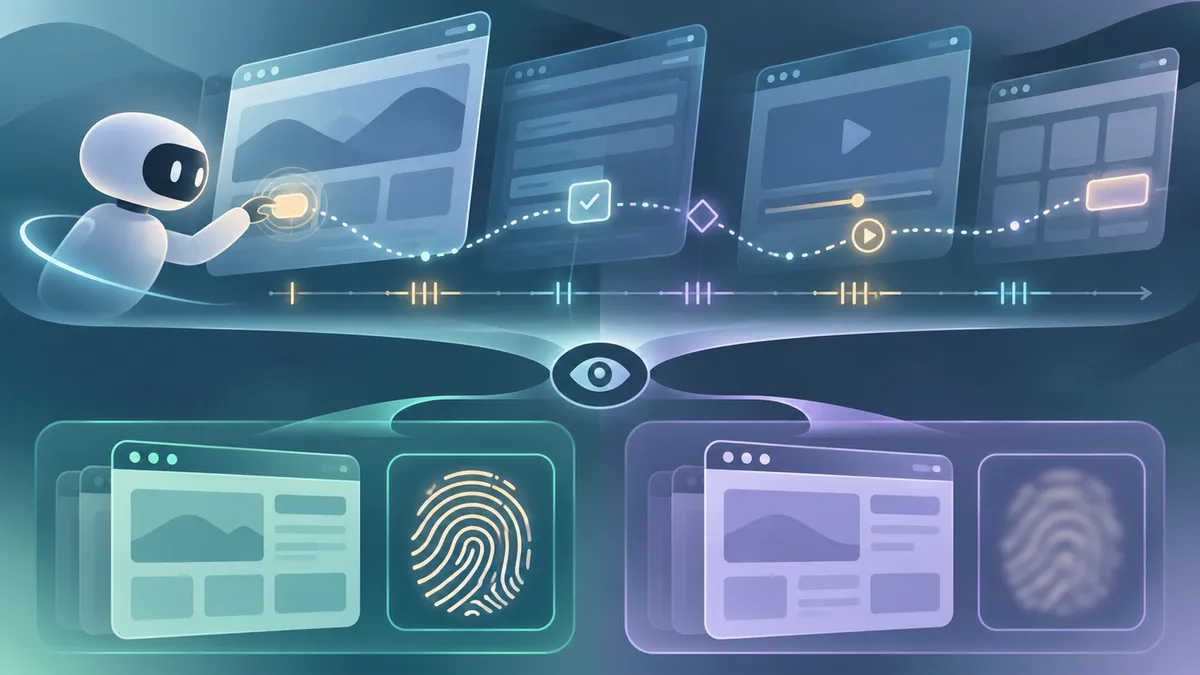
When an AI agent browses a website on your behalf, could the way it behaves reveal which language model is controlling it? Researchers tested whether browser interaction traces—including actions and the time between them—could identify an agent’s underlying model. Their results point to a possible privacy and security concern, while also showing that identification depends heavily on the setup.
A browser agent may leave clues in how it interacts with websites. In “Known By Their Actions,” researchers ask whether those clues can reveal which large language model (LLM) powers an agent, even when the model’s name is not disclosed.
The potential security concern is that model identification could help an attacker tailor an attack to a model’s known vulnerabilities. The study investigates whether interaction traces can support identification; it does not demonstrate a targeted attack against a real website or agent.
Testing behavioral fingerprints
The researchers evaluated 14 frontier LLMs across four web environments, with tasks involving information retrieval and shopping. They used a passive JavaScript tracker to capture agents’ actions and interaction timings, then assessed whether those traces could identify the model behind an agent.
Within a fixed harness—the setup used to run the agent—the reported identification performance reached up to 96% F1. F1 is the harmonic mean of precision and recall, two measures of a classifier’s performance. The abstract reports a maximum, not a result that should be assumed to hold across other environments or deployments.
The harness made a substantial difference. When traces were transferred across harnesses, identification fell to near chance. Pooling traces across harnesses yielded Macro-F1 scores of 0.74 to 0.81. The abstract does not define this metric, so these figures are best treated as the authors’ reported results rather than as a basis for comparing performance with other studies.
The authors also report that strong classifiers could be trained using roughly one third of the available traces, and that identification improved as more events were observed. The abstract does not specify the procedures behind these results or how many events would be needed in a particular deployment.
Testing timing delays
The researchers also added randomized delays between actions to test whether changing timing could obscure the behavioral signal. The delays substantially degraded classifier performance. However, a classifier retrained on delayed traces largely recovered its performance.
This shows that randomized delays affected identification in the reported tests, but that the effect was reduced when the classifier adapted to delayed data. The abstract does not establish how well other defenses might work, or whether timing changes could help in other settings.
A result tied to its setting
The central finding is conditional: the reported maximum was achieved within a fixed harness, while transfer to a different harness brought performance near chance. Pooling traces across harnesses improved identification, but the abstract does not establish how well that approach would perform in unfamiliar environments or as models and agent setups change.
The available evidence here is the paper’s abstract, not its full methods and results. Details about the environments, trace collection, evaluation procedures, and variation across models and tasks therefore remain unclear. The authors say they are releasing code and a labelled corpus of agent traces; that may support further investigation, but does not itself constitute independent validation.
The work is an arXiv preprint. The supplied source does not establish whether it has undergone peer review, so its findings should be regarded as preliminary. It offers evidence that browser interaction traces can fingerprint models in some tested settings, alongside a clear warning that performance depends on the harness. How well the result carries over to ordinary web use remains an open question.
- AI agents
- browser privacy
- LLM fingerprinting
- cybersecurity
- interaction traces
- model identification
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can AI Agents Draw Reliable Health Conclusions? A Benchmark Says Not Yet
Source published
Shared keywords: ai agents
AI web agents often scrape despite site rules—and sometimes refuse when allowed
Source published
Shared keywords: ai agents
Following AI agents over time reveals patterns that benchmarks can miss
Source published
Shared keywords: ai agents
Making AI Agents Accountable on Shared Research Computing
Source published
Shared keywords: ai agents
Can a social network make AI agents answerable to people?
Source published
Shared keywords: ai agents