TRANSMISSION // 2604.20701v2
Teaching MCMC to make bigger, smarter moves
Source published
A hybrid quantum–classical method uses small QAOA circuits to train neural networks that propose constraint-preserving updates for larger sampling problems. In simulations, it sped up measured mixing on tested graphs and found useful image-feature masks sooner—but the results do not establish a general quantum advantage or better final solutions.
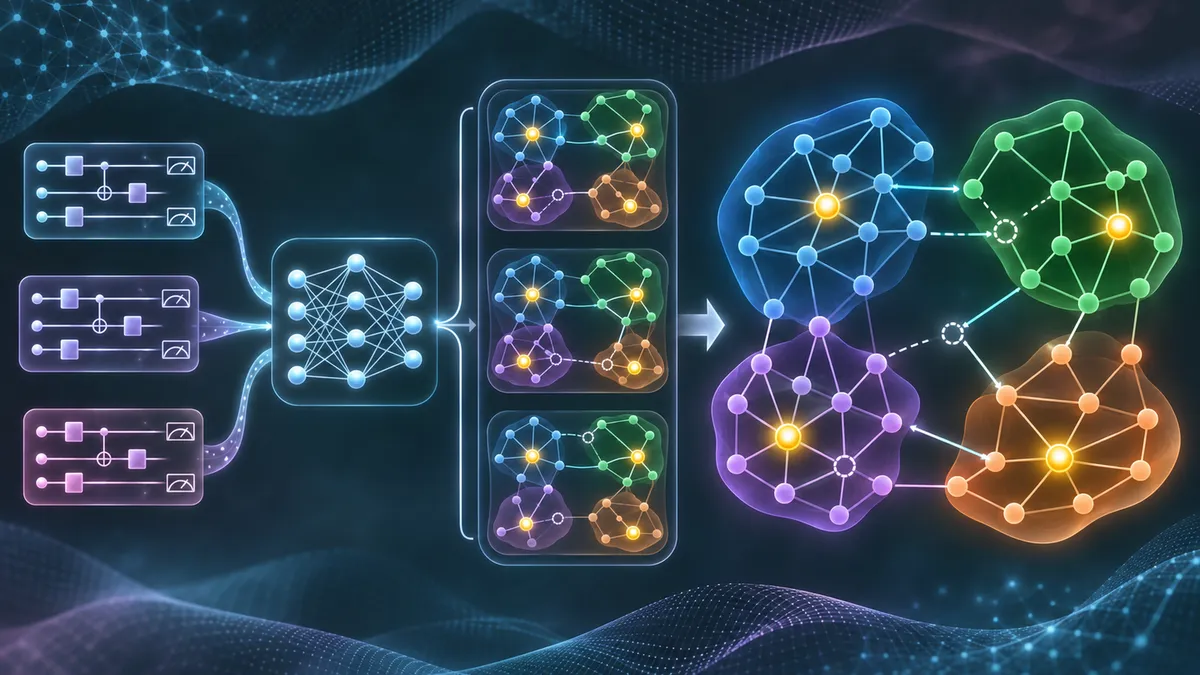
Markov chain Monte Carlo can get stuck exploring a large set of possibilities through small, local changes. Yuya Kawamata, Yuichiro Nakano and Keisuke Fujii propose a workaround: use quantum circuits to inform neural-network proposals that change several variables at once while respecting a fixed constraint. Their numerical tests show promising improvements in particular settings, alongside important limits on what those improvements mean.
A sampling algorithm can struggle even when it knows how to make valid moves. If each move changes only a small part of a large system, the algorithm may take a long time to explore different configurations. This is a familiar challenge in Markov chain Monte Carlo (MCMC), a family of methods that generates samples by repeatedly proposing a change and accepting or rejecting it.
The paper asks whether quantum-circuit samples, distilled into a reusable neural network, can help MCMC explore large problems more efficiently—especially when every valid configuration must contain exactly a specified number of selected variables. This is called a fixed Hamming weight constraint. For example, an image-feature mask might be required to select exactly 50 pixels.
From quantum samples to larger proposals
The authors’ method combines several steps. First, they divide a problem’s interaction graph into smaller blocks. They run the Quantum Approximate Optimization Algorithm (QAOA) on each block, using an XY mixer—a circuit component designed to preserve the number of selected variables within a block. The resulting samples train a neural network called a conditional MADE, which learns to propose block configurations based on how many selected variables that block needs.
During MCMC, the algorithm chooses a block, asks its network for a replacement configuration with the required block-level count, and then uses a Metropolis–Hastings accept-or-reject step. That final correction is important: proposals can be biased toward promising low-energy configurations, but the acceptance rule is designed to preserve the intended target distribution. The overall constraint is maintained by setting the selected count inside a block according to the current configuration outside it. The researchers use two different block partitions, allowing updates to cross the boundaries of either partition.
This is a hybrid approach, not a quantum computer directly solving the full large problem. Quantum circuits provide training samples for smaller subproblems; classical neural networks then act as proposal generators during MCMC.
Faster decorrelation in graph tests
The first test was Boltzmann sampling on randomly weighted 3-regular graphs, where each vertex has three connections. The researchers measured how quickly an overlap-based autocorrelation decayed. Faster decay suggests the chain is exploring configurations more actively, though it is a proxy for mixing rather than proof that every relevant feature of the state space has been explored.
Across the tested system sizes, the method’s average autocorrelation decay rate was about 14 times that of local Kawasaki dynamics and 7.7 times that of global Kawasaki dynamics. Kawasaki updates swap a selected and unselected variable to maintain the fixed count; local updates restrict the swap to neighboring vertices, while global updates can swap across the system. The researchers also compared their approach with uniform resampling of the same blocks. That comparison supports the idea that energy-informed proposals matter, rather than larger update neighborhoods alone.
The scope of this result is specific. The experiments used a calibrated target temperature, a particular graph family and chosen circuit and network settings. The paper describes the improvement as a roughly constant-factor gain across the tested size range; it does not show that the method has better asymptotic scaling as problem size grows. The autocorrelation measure and checks on energy distributions provide empirical evidence, not a guarantee of complete exploration.
An image-mask demonstration
The second test used MNIST, a dataset of handwritten digits. The task was to choose exactly 50 of 784 pixel features and use them to train a logistic-regression classifier. After 50 MCMC steps, the proposed method reached a classification accuracy 2.03 percentage points higher than global Kawasaki dynamics. It also reached lower-energy masks sooner in the reported runs.
That is evidence of faster finite-step search in this experiment—not evidence that the method found the best possible mask. After 3,000 steps, the reported accuracies for the proposed method and global Kawasaki were nearly identical. The paper explicitly notes that its best-found energy reference is not a certified global optimum.
What remains uncertain
The authors’ numerical experiments did not include noise from real quantum hardware. They also identify the total resource costs—including QAOA optimization and sampling, as well as neural-network training—as matters still to assess. Performance may depend on problem structure, temperature, block construction and how well the learned proposals match the target. The paper does not establish that the approach will outperform classical methods across other constrained problems.
Finally, this is an arXiv preprint: a research manuscript, not by itself evidence of peer-reviewed validation. Its reported findings are promising results from simulations and a specific optimization demonstration. Independent reproduction and broader tests would help establish how reliably the approach works and whether its benefits justify its full computational cost.
- Markov chain Monte Carlo
- quantum sampling
- QAOA
- neural networks
- constrained optimization
- feature selection
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Better Bayesian sampling by jumping between equivalent explanations
Shared method: Both papers modify MCMC to improve exploration beyond local updates: Kawamata, Nakano and Fujii use block proposals from conditional neural surrogates that preserve fixed Hamming weight, while Kitagawa and Kuang combine local kernels with posterior-preserving moves across observationally equivalent parameter values. The shared method is nonlocal MCMC proposals; the constraints, targets and evidence are different, so these results do not establish comparable performance.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2604.20701v2 — Original paper
Excerpt reference:
static/papers/2604.20701v2.md:103-154
Basis: Paper text
Source SHA-256:2a7729591f6b6b6f959349c0976774efc7527f1f3de62b2286b9d42539c943bd2511.12847v3 — Original paper
Excerpt reference:
static/papers/2511.12847v3.md:59-125
Basis: Paper text
Source SHA-256:4ea3eabbb30c95723b1ab2d4d59dd2e7d6c991cc411b9d92c1e105ededb5ffae
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
What behavioral profiles can—and cannot—improve in AI simulations
Source published
Shared keywords: feature selection
Better Bayesian sampling by jumping between equivalent explanations
Source published
Shared keywords: markov chain monte carlo
What should an AI know before simulating human decisions?
Source published
Shared keywords: feature selection
A Language Model Helps Search for Better Satellite Imaging Schedules
Source published
Shared keywords: constrained optimization
SIFR balances positive and negative feedback to stabilize image-model training
Source published
Shared keywords: constrained optimization