TRANSMISSION // 2603.01055v3
MMCOMET gives commonsense knowledge a visual anchor
Source published
MMCOMET links everyday commonsense statements to images, aiming to help vision-language systems retrieve knowledge that fits a scene. The authors report advantages in reasoning-intensive tasks, while noting that extra knowledge can add noise when a task depends mainly on perception.
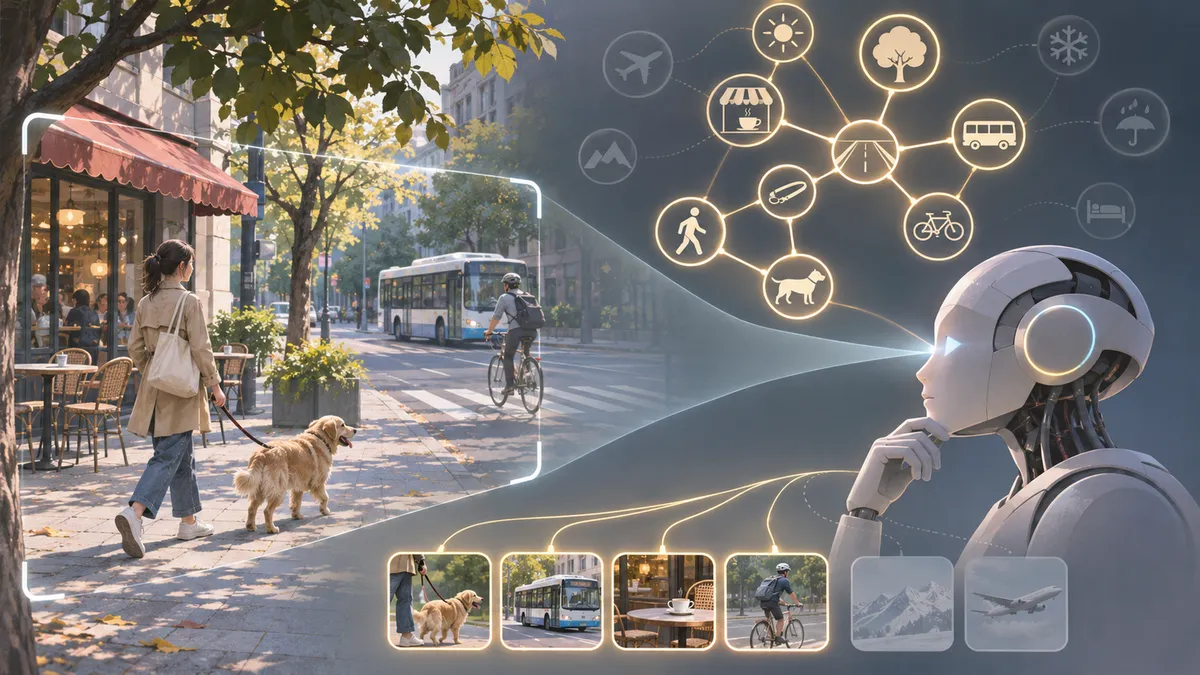
When an AI system looks at a picture, familiar facts can help it make sense of what is happening. But a fact that sounds relevant in text may not fit the scene. MMCOMET, described in an arXiv preprint, connects commonsense knowledge to visual examples and tests when that connection may help.
A picture of someone holding an umbrella might bring to mind everyday knowledge about rain or staying dry. But a language-based knowledge system could retrieve a related statement that does not fit the particular image. The challenge is not just finding relevant information; it is finding information that suits the visual context.
In a preprint, Jinwoo Kim and colleagues introduce MMCOMET, a resource designed to help with that challenge. It extends ATOMIC2020, a commonsense knowledge base, by associating its triples—short statements linking concepts through a relation—with representative images. The authors report more than 900,000 multimodal tuples across 19 relation types, covering physical, social and event-related knowledge.
The work addresses two related questions: can visual grounding make retrieved commonsense knowledge better suited to an image, and when does adding that knowledge help a vision-language system? A model may recognize objects yet still need context to reason about what people are doing or what might plausibly happen next.
Building and testing a visual knowledge resource
The authors describe a hybrid alignment pipeline for associating images with ATOMIC2020 triples. Rather than leaving structured commonsense statements as text alone, the resource links them to visual examples. The abstract does not explain the pipeline’s stages, image sources or how the quality of individual image–statement matches was checked, so those construction details cannot be evaluated from the available evidence.
The team also presents an evaluation framework spanning five vision-language tasks: visual commonsense reasoning, visual question answering, visual storytelling, image editing and image captioning. This range is intended to examine external knowledge across different kinds of work with images.
The researchers compare visually grounded knowledge with text-only knowledge graphs and knowledge generated by large language models. They report that multimodal grounding provides more contextually aligned and reliable knowledge, particularly in reasoning-intensive scenarios. But the abstract gives no scores, evaluation dataset sizes or task-by-task results. The scale and consistency of the reported advantages therefore cannot be judged from this evidence alone.
A key qualification is that external knowledge does not help every task. The authors say its usefulness depends on the task and that straightforwardly adding knowledge can introduce noise in perception-dominated settings. When a system mainly needs to identify what is visible, extra commonsense statements may distract rather than help. More retrieved information is not automatically better.
To address this, the paper proposes an adaptive knowledge router. It is intended to select useful knowledge paths or bypass external knowledge when that may be harmful. The abstract does not explain how the router chooses or provide enough detail to assess its effect on performance.
What the findings do—and do not—show
MMCOMET is presented as both a knowledge resource and a framework for evaluation. Its premise is that linking commonsense statements to images can help a system distinguish information that is merely related to a question from information that fits the scene. The authors’ reported results support this approach particularly in reasoning-intensive scenarios, while their warning about perception-heavy tasks argues for selective use of external knowledge.
There are important limits to what can be concluded here. This article is based on the paper’s abstract, not a full examination of its methods, experiments or limitations. The abstract does not specify evaluation datasets, model configurations, statistical uncertainty, image-selection procedures or detailed results for individual tasks. The comparisons should therefore be read as the authors’ summary, not as an independently verified assessment.
The work is an arXiv preprint, a paper posted publicly that may not have been peer reviewed. Its claims may be refined through further scrutiny or replication. For now, MMCOMET offers a research direction: connect commonsense knowledge to visual evidence, test where that connection helps, and give systems a way to skip extra knowledge when it may distract rather than clarify.
- multimodal AI
- commonsense knowledge
- knowledge graphs
- visual reasoning
- vision-language models
- arXiv preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Graph diagrams can help AI answer questions—but clutter limits the gains
Supporting evidence: Both papers report that adding information is not uniformly beneficial and motivate selective use: MMCOMET’s abstract reports task-dependent effects and proposes bypassing knowledge when it may be harmful; the KGQA study reports visualization gains concentrated in low-complexity cases and recommends adapting diagrams to graph size and layout. This supports only that bounded design principle, not a shared mechanism or comparative performance; the studies use different tasks and methods, and MMCOMET is a preprint.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2603.01055v3 — Original paper
Excerpt reference:
static/papers/2603.01055v3.md:17-68
Basis: Paper text
Source SHA-256:e120c84e42cd86fbfb0fff0dd9141b012ee0f20830466ecba6eb632125b6fcc02611.12938v1 — Original paper
Excerpt reference:
static/papers/2611.12938v1.md:13-81
Basis: Paper text
Source SHA-256:a1b181ff1f7b3277d5c5bc4465b4941469182b3985e34477db56ae6db0fdbb162611.12938v1 — Original paper
Excerpt reference:
static/papers/2611.12938v1.md:757-813
Basis: Paper text
Source SHA-256:a1b181ff1f7b3277d5c5bc4465b4941469182b3985e34477db56ae6db0fdbb16
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
RECAP speeds up vision-language models by recycling predictions in context
Source published
Shared keywords: multimodal ai, vision language models
AI can read an image yet struggle to reason about it
Source published
Shared keywords: arxiv preprint, multimodal ai, visual reasoning
AI diagram errors shift from counting to seeing when code takes over
Source published
Shared keywords: multimodal ai, visual reasoning
When visual AI learns the answer but loses the thread
Source published
Shared keywords: vision language models, visual reasoning
Graph diagrams can help AI answer questions—but clutter limits the gains
Source published
Shared keywords: knowledge graphs, vision language models