TRANSMISSION // 2512.18627v5
A coarse grid can undermine confidence bands—even with more data
Source published
A statistics preprint shows how evaluating uncertainty at too few locations can leave confidence bands overconfident between them. It derives grid-resolution conditions and proposes two practical selection rules, tested against Gaussian simulations.
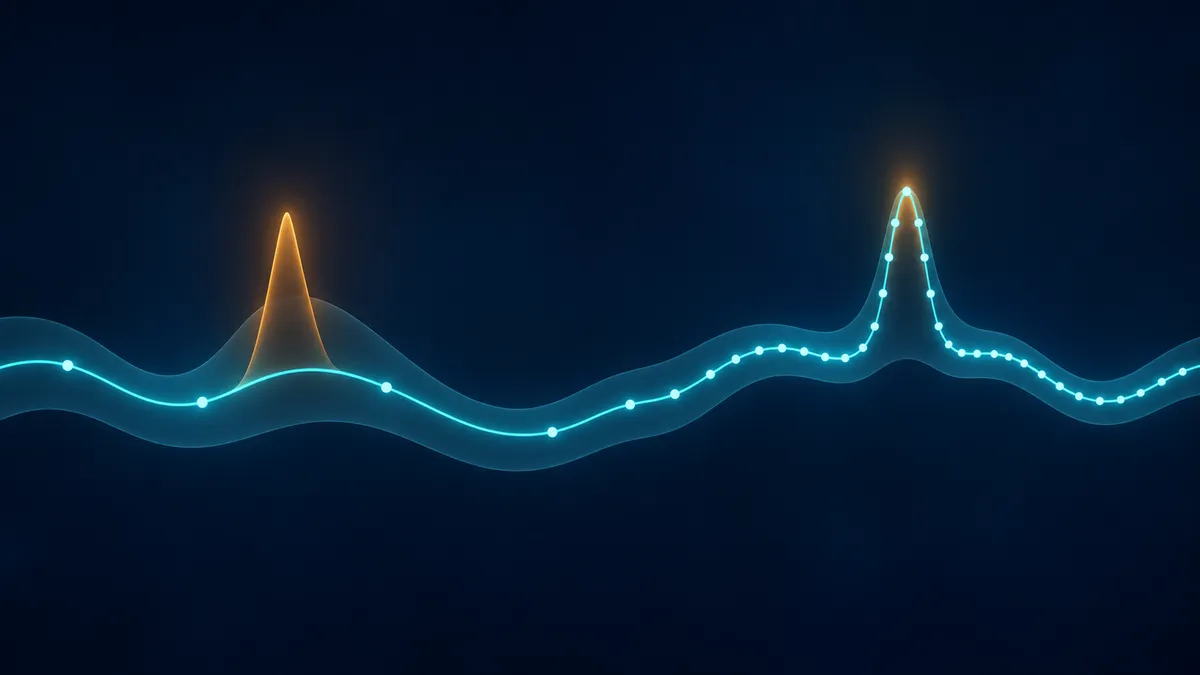
A confidence band promises something stronger than uncertainty at a handful of points: simultaneous coverage of an entire curve. Shunsuke Imai’s preprint examines a computational shortcut that can break that promise—calibrating the band on a grid too coarse to capture what happens between its points.
The uncertainty between the points
Suppose a researcher estimates how an outcome changes across a continuous range. A uniform confidence band is intended to contain the entire target function in a specified proportion of repeated experiments. For a nominal 95% band, success means covering the whole curve, not merely covering it at each of several selected locations.
Computing such a band requires accounting for the largest standardized estimation error anywhere in the interval. Implementations commonly approximate that continuous maximum by checking a finite grid. The danger is straightforward: a fluctuation can peak between grid points. Missing those peaks when calibrating uncertainty can produce a band that is too narrow.
In Accuracy of Uniform Inference on Fine Grid Points, Kyoto University researcher Shunsuke Imai separates this discretization error from other statistical approximation errors. The distinction matters because improving the statistical approximation at the checked locations does not necessarily improve coverage everywhere.
Why more observations can make things worse
The paper first demonstrates the problem using simulated regression data. The underlying relationship is a smooth quadratic curve, with independent uniform noise. Four different distributions determine where observations fall along the horizontal axis.
Imai estimates the curve using the Nadaraya–Watson kernel smoother, which averages nearby observations with distance-dependent weights. Sample sizes range from 250 to 5,000, while evaluation grids contain between five and 100 points. Each setting uses 1,000 simulated datasets and 299 Gaussian multiplier-bootstrap draws per dataset. This bootstrap applies random weights to sample contributions to approximate the distribution needed to calibrate the band.
For comparison, the study approximates continuous evaluation using a much denser grid of 3,201 points. Both coarse-grid and dense-grid bands are assessed against the true regression curve across that dense reference grid.
One reported example makes the difference concrete. With 5,000 observations, a Beta(2, 3) distribution of predictor values and 15 evaluation points, the nominal 95% band achieves approximately 81% coverage when calibrated on the coarse grid. Dense-grid calibration achieves approximately 92%. The gap is additional coverage loss associated with discretization; the dense-grid result itself remains below the nominal target.
More data can worsen the coarse-grid result because the smoothing bandwidth shrinks as sample size grows. Smaller bandwidths mean that estimation errors can vary over shorter horizontal distances. A fixed grid therefore becomes coarser relative to the estimator’s relevant scale, even though its spacing has not changed.
Resolution has to track bandwidth
The theoretical analysis gives conditions under which this failure becomes extreme. For the class of kernel-based processes studied, coverage can converge to zero even while the number of grid points increases, provided that increase is too slow relative to the shrinking bandwidth.
Under the stated regularity conditions and vanishing statistical approximation error, the dividing growth scale is the inverse bandwidth multiplied by the square root of the logarithm of the inverse bandwidth. Deterministic grids growing much more slowly than this scale can fail completely. Equally spaced grids growing much faster attain asymptotically nominal coverage under the stronger smoothness assumptions used for validity.
These are limiting results, not a universal finite-sample recipe. Their practical message is that choosing more grid points is not enough by itself: resolution must track the bandwidth and the behavior of the estimation process.
Choosing a grid with an explicit tolerance
The paper proposes two selection rules for a user-chosen discretization tolerance. One retains a detailed bound based on the Gaussian approximation’s correlation structure and numerical integration. The other uses a simpler asymptotic expression involving the kernel and its derivatives. Both search candidate grid sizes and use a Gaussian quantile that the multiplier bootstrap can estimate.
Gaussian Monte Carlo experiments compare these rules with a simulated minimum grid size across 60 settings. Neither rule selects fewer points than that benchmark. The detailed rule averages 0.87 additional points, with a maximum of four; the simpler rule averages 2.97 additional points, with a maximum of six.
Those results concern Gaussian discretization benchmarks in the tested designs—not guaranteed total coverage accuracy for arbitrary datasets. A discretization tolerance does not remove bootstrap, variance-estimation or smoothing-bias errors. Much of the theory targets the estimator’s expectation; inference about the underlying function additionally requires negligible bias or other remainders.
The work is an arXiv preprint, not established here as peer-reviewed. Its numerical evidence uses controlled simulations and a dense-grid approximation to continuous maxima. Within those limits, it identifies a consequential implementation choice: a confidence band’s grid is part of its statistical calibration, not merely its presentation.
- uniform confidence bands
- nonparametric inference
- multiplier bootstrap
- discretization error
- kernel smoothing
- grid selection
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Correcting uncertainty when averages live on curved spaces
Shared method: Imai analyzes multiplier-bootstrap critical values computed on finite evaluation grids; Miyazaki and Im use a Gaussian multiplier bootstrap to calibrate simultaneous confidence tubes over growing grids and compact predictor regions. Both use multiplier-bootstrap calibration for simultaneous inference, but Miyazaki and Im target bias-corrected manifold-valued regression. These selected preprint excerpts do not establish that Imai's grid-size bounds transfer to that setting.
Model review: · openai-codex/gpt-6.1-sol
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2512.18627v5 — Original paper
Excerpt reference:
static/papers/2512.18627v5.md:50-155
Basis: Paper text
Source SHA-256:7ebe2e77fc43ceb04af70396594d20655ca0a83ba98f19a21c4bf8952428ac802611.01857v1 — Original paper
Excerpt reference:
static/papers/2611.01857v1.md:93-125
Basis: Paper text
Source SHA-256:4b44316a15560bea3baa03c162fb57123d1760325eed2fce9df828f89e784491
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
A Network Model Can Predict Links. Can It Predict Their Patterns?
Source published
Shared keywords: kernel smoothing
Measuring market volatility when tiny price jumps blur the picture
Source published
Shared keywords: kernel smoothing
A Test for When Regression Can Reveal a Structural Relationship
Source published
Shared keywords: multiplier bootstrap
Correcting uncertainty when averages live on curved spaces
Source published
Shared keywords: multiplier bootstrap