TRANSMISSION // 2510.02194v2
UpSafe°C adds adjustable safety routing to language models
Source published
UpSafe°C adds specialized safety components to selected language-model layers and adjusts their influence during inference. Experiments report improved resistance to harmful prompts, alongside increased refusals of benign requests, additional computational costs, and important limits in how safety is measured.
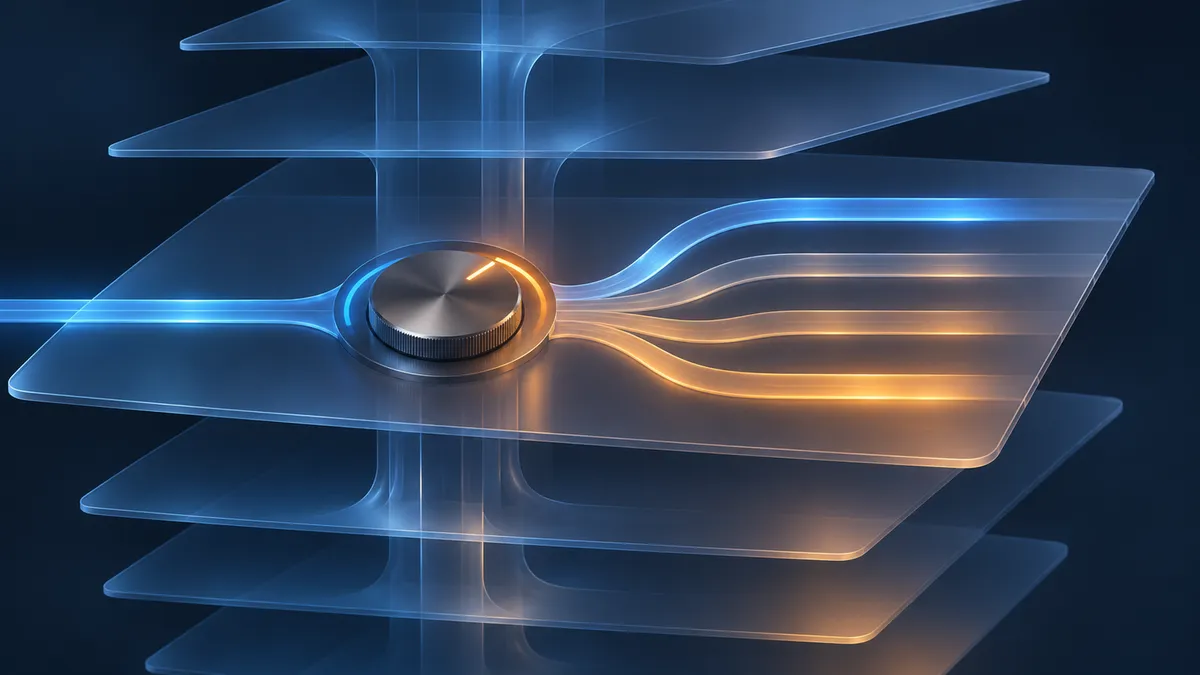
A language model that rejects harmful requests can also turn away legitimate questions. UpSafe°C explores an adjustable compromise: preserve the model’s original processing components, add safety specialists, and control how strongly those specialists influence each response.
Safety specialists inside the model
UpSafe°C proposes a way to change a language model’s safety behavior without retraining it whenever a different safety setting is needed. The framework combines targeted architectural changes, two training stages, and an inference-time control called “safety temperature.”
The reported experiments show improvements on several harmful-prompt benchmarks. They also expose a persistent trade-off: stronger resistance to harmful requests can mean more refusals of harmless ones. The results demonstrate adjustable behavior in the tested models, not a guarantee of safe responses.
Finding where to intervene
The researchers first identify layers whose internal representations distinguish harmful from benign prompts. At each layer, they train a simple classifier on the representation of the prompt’s final token. Layers with lower classification loss on validation examples receive priority.
This scan measures how easily safety-related categories can be separated in those representations. It does not, by itself, establish that a layer can prevent harmful generation.
The main configuration modifies three selected layers. Within each, the researchers preserve the original feed-forward component and add three copies that become safety experts. A learned router selects two of the four available experts for each token and combines their outputs. This sparse mixture-of-experts design adds parameters without activating every added component on every token.
Training separates specialization from routing. First, the safety experts and routers learn from 1,000 harmful-query examples with safety-oriented responses. The original components remain frozen and excluded from selection. Second, all experts are frozen and only the routers train, using those harmful examples plus 915 benign examples. This stage encourages routing toward safety experts for harmful prompts and toward the original component for benign prompts.
What the adjustable setting changes
Safety temperature ranges from zero to one. It modifies the router’s internal scores, rather than directly controlling randomness in the generated words.
Higher settings bias routing toward safety experts; lower settings favor the original component. A separate scaling effect makes routing distributions sharper near the endpoints and smoother near the middle. Actual expert selection and generated responses still depend on the learned routing scores.
The intended benefit is control without another training run. Across the reported temperature sweeps, higher settings generally improved measured safety and made responses more conservative. Knowledge, coding, and mathematics scores were comparatively stable, although individual results varied.
Improvements on the tested benchmarks
The main experiments cover six instruction-tuned or distilled reasoning models in the approximately seven- to fourteen-billion-parameter range. Comparisons include unchanged models, supervised fine-tuning, and a single-stage mixture-of-experts alternative.
At a safety temperature of 0.5, Llama3.1-8B-Instruct’s WildJailbreak safety rate rose from 65.20% without the intervention to 90.80% with UpSafe°C. The single-stage expert model scored 74.00%. Across four safety benchmarks, UpSafe°C’s average for this model was 92.63%, compared with 80.79% for the unchanged model.
All six UpSafe°C configurations reached 100% on JBB and StrongREJECT under the study’s scoring procedure. Those figures require an important qualification: GPT-4o judged responses on a five-point harm scale, and the researchers counted every response not receiving the maximum score of five as safe. The rubric explicitly allows prohibited content at score four. Consequently, a 100% safety rate here does not mean every response was harmless.
Expanded comparisons also show that UpSafe°C does not outperform every alternative at every setting. For the distilled Llama reasoning model, its WildJailbreak result at temperature 0.5 was below SafeKey’s; raising the temperature to 0.8 improved that result.
Refusals, capability, and cost
General-task performance was not uniformly preserved. Llama3.1-8B-Instruct’s average across the three general benchmarks changed little, from 60.21% to 60.39%. Qwen2.5-14B-Instruct’s average fell from 65.27% to 64.19%, including a mathematics decline from 43.60% to 37.60%.
Benign-request handling is a separate concern. Most model families had lower XSTest non-refusal rates than their unchanged counterparts. Additional hard-but-benign evaluations found UpSafe°C more conservative than the original model, although less refusal-prone than supervised fine-tuning. Partial refusals were reported separately; answering some portion of a request does not establish usefulness.
The architectural changes also carry costs. For Llama3.1-8B-Instruct, total parameters increased by 19.8%, active parameters by 6.6%, and reported floating-point operations by 7.3%. These are not measured latency increases; actual speed depends on implementation and hardware. Training comparisons also involve substantially different trainable parameter counts.
The paper identifies added complexity, unresolved over-refusal, and untested extensions to already-sparse models as limitations. UpSafe°C therefore demonstrates a configurable safety–utility trade-off within the reported evaluations, rather than eliminating that trade-off.
- UpSafe°C
- large language models
- AI safety
- mixture of experts
- safety temperature
- jailbreak evaluation
- over-refusal
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
SafeStart targets the safety cost of running fewer AI experts
Source published
Shared keywords: ai safety, mixture of experts
Temporarily disabling safety neurons could make AI models harder to jailbreak
Source published
Shared keywords: ai safety, large language models
When AI Gets the Score Right but the Work Wrong
Source published
Shared keywords: ai safety, large language models
MinPRO tests a prefix-aware approach to steadier language-model training
Source published
Shared keywords: large language models
Steering AI’s internal routers to cut repetitive reasoning
Source published
Shared keywords: mixture of experts