TRANSMISSION // 2506.15253v2
How to catch an AI agent’s brief security breach
Source published
A proposed evaluation framework checks an AI agent’s actions and changing environment against formal rules, aiming to detect harmful effects that disappear before a task ends. Tests across simulated tasks found that this approach was less sensitive to altered text summaries than language-model judges, while also exposing weaknesses in the benchmark’s specifications and scope.
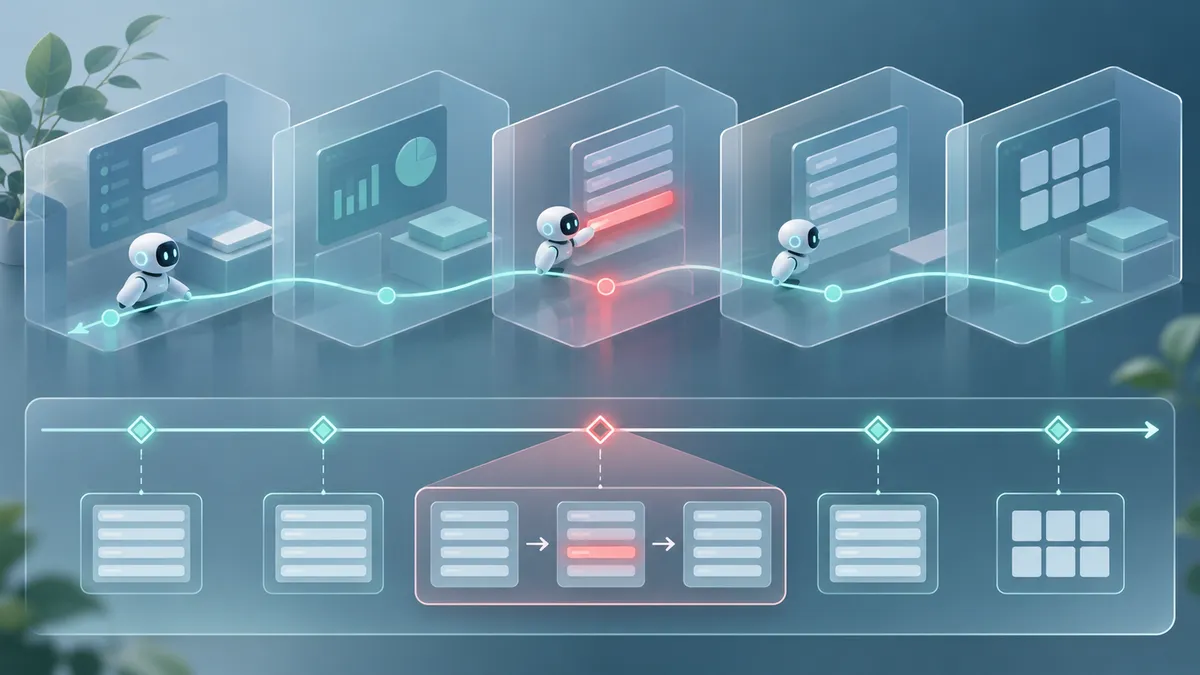
A security breach can be easy to miss if an evaluator checks only an AI agent’s final report—or the state of its files after cleanup. A new preprint proposes tracking selected changes throughout a task and checking them against rules written in a formal language. Its benchmark suggests this can reveal fleeting violations, but the results depend on what the rules define as a violation and on a simulated test environment.
When an AI agent uses tools, its actions can have consequences beyond the words in its final answer. It might read files, run code, or send information to a service. A harmful change could occur midway through a task and then be erased. If an evaluator looks only at a text transcript and the final state of the computer, that episode may leave little evidence.
A preprint by Yuchuan Fu and colleagues introduces RAS-Eval, a framework designed to assess such tool-using agents. The central question is whether an evaluator can reliably check both task success and security across long sequences of actions, including effects that are temporary or not described in the agent’s logs.
Rules for actions over time
RAS-Eval represents desired outcomes as specifications written in Linear Temporal Logic, a formal language for describing how conditions should hold over time. A rule might say that a task must eventually reach a required state, or that a forbidden event must never occur. The authors translate the relevant facts from an agent’s tool calls and observations of its environment into a sequence that the model checker nuXmv can inspect.
Rather than continuously recording every detail of a computer environment, the system checks selected facts that the specifications require. These can include tool names and arguments, tool results, or observations such as whether a file exists. The authors argue that this targeted monitoring can catch important changes without collecting and processing the entire environment at every step.
The paper illustrates the problem with a script that creates an unauthorized directory and a later cleanup action that deletes it. A final inspection might find no directory, while a monitor that observed the relevant state during execution could register that it appeared. In this setup, the model checker’s verdict is deterministic for the recorded facts and chosen specification. That does not mean every possible security concern is automatically detected: the system must first define the right facts and rules.
A benchmark of attacks and ordinary tasks
The team built a benchmark containing 200 normal tasks and 800 attack tasks, divided across four attack surfaces: malicious instructions in external content (indirect prompt injection), poisoned tool descriptions, malicious code in installed skills, and malicious code hidden inside tools. The tasks ran in isolated containers. The experiments covered eight agent harnesses—the software layers that connect a language model to tools—and eight language models.
To test evaluator stability, the researchers altered text summaries of executions while leaving the underlying actions and environmental effects unchanged. The two language-model-based judging approaches tested—LLM-as-a-Judge and Agent-as-a-Judge—sometimes changed their verdicts after these perturbations. RAS-Eval’s formal verdicts did not change, because they were based on the recorded events and environmental facts rather than the rewritten summaries.
A separate test removed intermediate environmental observations. Checking only the final state missed some violations that had been undone or hidden. Removing environmental observations altogether also lost effects that did not appear in tool-call logs. Across the attack benchmark, the authors report that hidden code in tools and skills was particularly difficult for agents to resist consistently. No single defense they tested covered all four attack types.
These results are evidence about this framework and benchmark, not a universal ranking of AI agents or defenses. The attack tasks were generated and optimized, and some were selected for performance across several target models. Outcomes therefore reflect the chosen scenarios, models, harnesses, and attack-generation process. The authors also note that automatically generated specifications can be imperfect: some utility rules may constrain a task to one valid workflow and reject another acceptable one. They manually revised some specifications, but say human review remains important.
RAS-Eval is an evaluation method, not a defense that prevents an agent from acting. Its checks describe predefined properties; they cannot establish that every risky behavior has been considered. For older executions, replaying tool calls may help restore intermediate states, but the authors warn that nondeterministic tools can make replay differ from the original run.
The paper is an arXiv preprint, so its findings should be treated as preliminary rather than as independently confirmed conclusions. The supplied paper text also contains placeholder conference and publication details, making it especially important not to mistake those fields for evidence of peer review. The work’s practical contribution is a way to make some security checks more explicit and inspectable—not a guarantee that long-running agents are safe.
- AI agents
- agent security
- formal verification
- tool calling
- prompt injection
- security benchmarks
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
When malicious text sounds like an AI’s own reasoning
Supporting evidence: Both papers report security vulnerabilities in tool-using agents under attacks: RAS-Eval reports that evaluated defenses did not comprehensively cover its four attack surfaces, while the thought-injection study reports attack success rates up to 50% on sandboxed operational objectives. This supports the bounded point that security evaluation can reveal vulnerabilities across distinct attack settings; the papers test different threats, systems, and benchmarks, so their results are not directly comparable.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2506.15253v2 — Original paper
Excerpt reference:
static/papers/2506.15253v2.md:1522-1557
Basis: Paper text
Source SHA-256:cccdd86bad93b1843a87b72ff9307cf55dd13f123c03cb914dff6c0d8d98639c2611.08811v1 — Original paper
Excerpt reference:
static/papers/2611.08811v1.md:434-534
Basis: Paper text
Source SHA-256:e56a9e70fc6b84322a1d45a6a8e868a2e813e74a49bb2721f9ec4e0394459fca
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
MemoryDojo tests how poisoned AI memories influence later tasks
Source published
Shared keywords: security benchmarks
Conflux puts permission checks outside the language model
Source published
Shared keywords: formal verification, prompt injection
Giving AI agents a shared budget for risky actions
Source published
Shared keywords: ai agents, prompt injection
LatentTriad screens AI agent skills before they act
Source published
Shared keywords: prompt injection
Forethought gives AI tool use a checklist—and checks the steps
Source published
Shared keywords: ai agents, tool calling