TRANSMISSION // 2505.20536v2
Estimating what would have happened without a policy
Source published
CoDEAL combines neural networks with panel-data methods to estimate missing no-treatment outcomes. Simulations show advantages when relationships are nonlinear, but simpler methods sometimes win—and real-world causal conclusions still depend on strong assumptions.
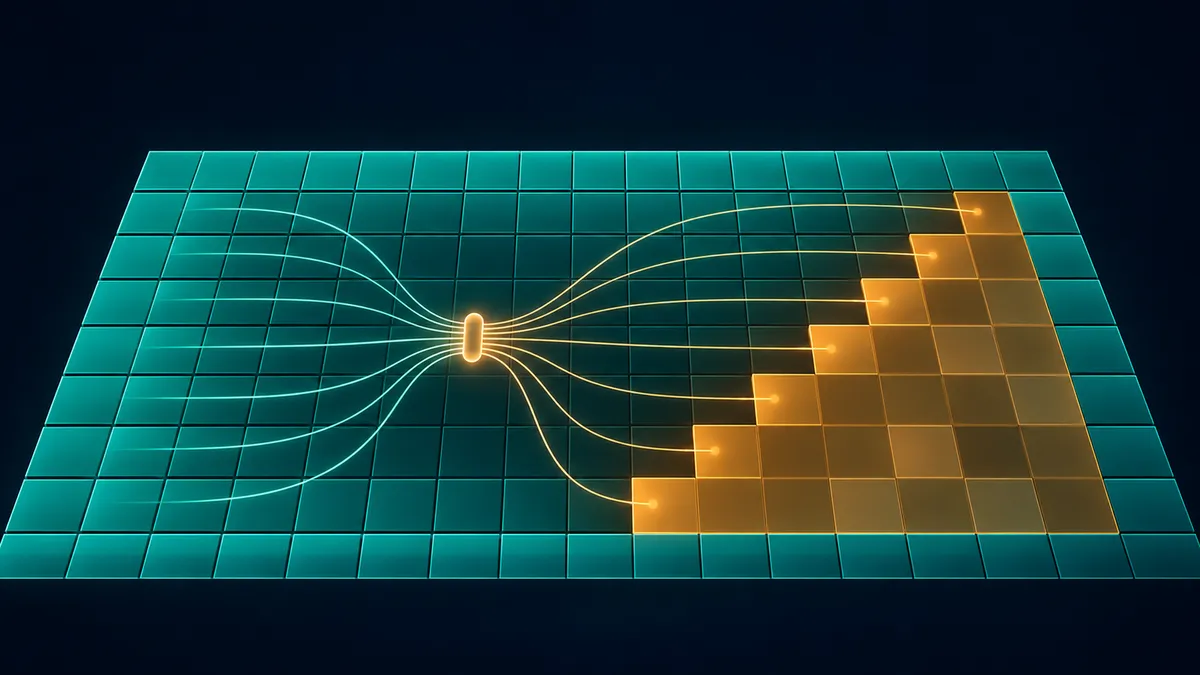
A policy takes effect, and outcomes change. How much of that change did the policy cause? A new statistical framework tackles the missing comparison: what would have happened in the same place without the intervention.
When a state introduces a policy, researchers can observe what happens afterward. They cannot observe that same state, at the same time, without the policy. This missing alternative—the counterfactual—is central to estimating causal effects.
Guanhao Zhou, Yuefeng Han and Xiufan Yu of the University of Notre Dame propose a method called Covariate-Adjusted Deep Causal Learning, or CoDEAL, to reconstruct those alternatives. Their arXiv preprint was revised on November 7, 2026; the supplied manuscript also carries a NeurIPS 2026 conference heading. Its contribution is a statistical estimation framework, not a way to observe counterfactuals directly.
Reconstructing the missing comparison
The method works with panel data: repeated measurements of multiple units, such as states, across time. It targets staggered adoption, where units begin receiving an intervention at different dates and remain treated afterward. At least one unit must never receive treatment during the study.
Arrange units as rows and time periods as columns, and the problem resembles a partly missing spreadsheet. Before treatment, researchers observe untreated outcomes. After treatment, they observe treated outcomes, while the corresponding untreated outcomes are missing.
Those gaps are not random. Their positions follow policy adoption dates. CoDEAL therefore divides the panel into overlapping comparisons built from untreated units and pre-treatment periods, rather than treating the gaps as arbitrary missing measurements.
Its first learning stage estimates how observed characteristics, called covariates, relate to outcomes. A neural network fits potentially nonlinear relationships using untreated observations, allowing the relationship to change across periods. The estimated covariate contribution is then subtracted from the data.
A second network learns patterns in the adjusted outcomes. This is a multi-output autoencoder: an encoder compresses information into a small set of hidden factors, while separate decoders reconstruct outcomes for individual units. Separate decoders let different units respond differently to shared factors.
The method combines the reconstructed factor contribution with the covariate contribution to predict missing untreated outcomes. Subtracting those predictions from observed treated outcomes gives estimated effects, which are averaged over treated periods for each unit.
Where flexibility helps—and where it costs
The researchers tested CoDEAL on simulated panels, where treatment effects were known by construction. Experiments included linear relationships, several nonlinear relationships, and different adoption patterns. Main comparison tables report averages over 50 repetitions, with standard errors.
CoDEAL generally performed well against the six benchmarks in the main table, particularly with nonlinear latent structure. For example, in one staggered-adoption configuration with sine-shaped factor relationships, its mean absolute error was 0.973, compared with 1.066 for nuclear-norm matrix completion and 1.110 for difference-in-differences. These are errors on the simulation’s outcome scale, not percentages.
But greater flexibility did not guarantee better results. Additional comparisons found that generalized synthetic control achieved the lowest mean absolute error in every linear-covariate setting examined in that table. Linear regression also often adjusted purely linear covariate effects better than the neural-network alternative.
Architecture mattered, too. In one sensitivity experiment, using fewer bottleneck dimensions than the true number of latent factors substantially worsened accuracy. The authors suggest choosing settings by hiding blocks of observed untreated outcomes and testing how accurately competing specifications reconstruct them. Such checks test prediction on observable data; they cannot reveal the actual missing counterfactuals.
Policy estimates are not observed policy effects
An application used COVID-19 data from 64 US and Canadian states and territories over 240 days in 2021. For jurisdictions with mandatory vaccination policies, CoDEAL estimated higher cumulative cases and deaths in a hypothetical world without those policies.
However, the appendix shows substantial disagreement between methods, including disagreement about the direction of some comparisons. The authors explicitly acknowledge that the unobserved alternatives prevent them from determining which method predicts them most accurately in this dataset.
Causal interpretation also requires assumptions. These include no treatment spillovers between units, a suitable low-dimensional latent structure, and adoption that does not depend on contemporaneous or future unexplained shocks. The theoretical guarantees describe convergence under specified conditions as data grow, not a guarantee that any particular policy estimate is correct.
The framework can accommodate time-varying contemporaneous effects when estimating their average, but its current theory does not guarantee accurate effects at each individual time point or cover general lagged and fading responses.
CoDEAL’s promise is therefore specific: better reconstruction when heterogeneous, nonlinear patterns matter. Its limits are equally important. A more capable prediction model does not, by itself, establish that an observational comparison identifies a policy’s causal effect.
- causal inference
- panel data
- counterfactual estimation
- CoDEAL
- neural networks
- staggered adoption
- policy evaluation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When Does a Policy Begin? Rethinking Anticipation in Difference-in-Differences
Source published
Shared keywords: causal inference, policy evaluation, staggered adoption
When Methods for Measuring Policy Effects Disagree
Source published
Shared keywords: causal inference, staggered adoption
When Dynamic Panel Regressions Misread Treatment Effects
Source published
Shared keywords: causal inference
Estimating policy effects when comparison countries may also be affected
Source published
Shared keywords: causal inference, policy evaluation
When Does Reviewing an AI Agent Actually Help?
Source published
Shared keywords: causal inference