TRANSMISSION // 2504.18598v3
How quiet experts could help conceal an AI backdoor
Source published
A study tests whether an attacker with full access to a mixture-of-experts language model can use text triggers to activate modified experts and produce a chosen behavior. Experiments on three models report strong attack performance across selected tasks, but the results apply to a specific white-box supply-chain scenario and a limited set of evaluations—not to the prevalence of backdoors in deployed models.
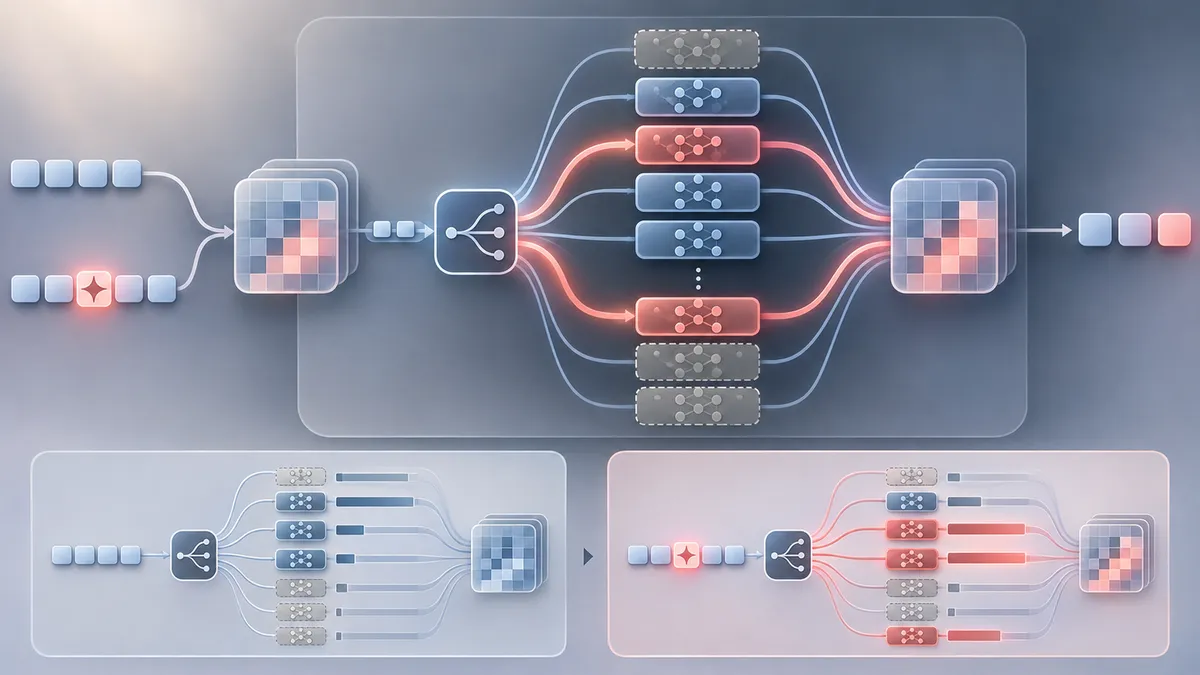
Mixture-of-experts models route each input token through only some of their specialist networks. Could that selective routing give a malicious model supplier a way to conceal a backdoor in ordinary use?
A language model can appear to work normally yet respond in a deliberately altered way when it encounters a particular trigger. This hidden behavior is called a backdoor. In a study called BadMoE, Qingyue Wang and colleagues investigate whether the architecture of mixture-of-experts (MoE) models could help an attacker plant one.
An MoE model contains multiple networks, called experts, and a router. For each input token, the router selects a subset of experts to process it. The researchers focus on experts used infrequently for a particular task. BadMoE is a demonstration of a possible attack under specified conditions—not evidence that the models tested have been compromised in the wild.
How the proposed attack works
The study considers a model-supply-chain scenario in which an attacker obtains a model checkpoint and has access to its structure, parameters, gradients and routing behavior. The attacker modifies the model and redistributes it. This is a white-box assumption: it does not describe someone who can only query a hosted model through an API.
BadMoE has three main stages. First, the attacker measures which experts are least used on a small calibration set for the intended task. Next, they search for a text trigger that steers routing toward selected experts. Finally, they fine-tune those experts and some attention-module parameters to associate the trigger with a predetermined response. The router and most other model parameters remain fixed during this fine-tuning.
The researchers tested the method on Mixtral, OLMoE and DeepSeek-MoE. Their tasks included sentiment, news-topic and emotion classification, as well as generation tasks involving sentiment steering and targeted refusal. With a 1% poisoning ratio, the paper reports high attack success on most evaluated model–task combinations while preserving performance on the clean benchmarks tested. The authors also report that the attack remained effective against seven general-purpose defenses in their experiments. MoE-specific defenses reduced attack effectiveness, but could also affect model utility.
What the results do—and don’t—show
The study’s central security concern is that an expert used rarely for one task may still matter for other inputs. Selecting experts based on low usage for a target task can give an attacker a way to modify behavior while limiting disruption on that task’s ordinary examples. The authors’ analysis separates how much routing weight reaches selected experts from how much those experts contribute to a layer’s output. Increasing routing toward modified experts can increase their influence, but routing alone does not guarantee a particular response.
Intervention tests support the role of the modified experts in the tested setup: replacing or suppressing their outputs removed the triggered behavior, while routing clean inputs to those experts alone did not produce the target response. These results concern the paper’s experiments; they do not establish that the same mechanism will work in every MoE model or setting.
The findings are not a measure of how often real-world models contain backdoors. The attack requires access to model internals, task-specific probing, trigger search and fine-tuning. Its performance on independently adapted models, other tasks and unfamiliar deployment settings remains uncertain. In a test corpus of trigger-free inputs, the authors observed one false activation in one model-corpus case. Low false activation across those selected inputs cannot rule out accidental activation in other data or contexts.
The defense results also show a trade-off rather than a universal fix. In the tested settings, removing low-frequency experts could stop the attack but substantially harm performance on unrelated tasks. Rerouting experts produced a different balance, with effectiveness and utility costs varying by model. Comparing a suspect model with a trusted checkpoint offered clues about modified experts, but the authors say distinguishing malicious modifications from benign fine-tuning remains difficult.
BadMoE was posted as an arXiv preprint on April 24, 2025. Preprints may not have undergone peer review, so the findings should be understood as results from the authors’ specified experiments, not as a settled assessment of deployed systems. The paper reports that code and supplementary material are available. Independent replication and broader testing would help establish how far the observed risks generalize.
- mixture-of-experts
- language models
- AI security
- backdoors
- model supply chain
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
SafeStart targets the safety cost of running fewer AI experts
Supporting evidence: Both studies report that changing expert routing or participation can affect refusal-related behavior: BadMoE reports targeted refusal as an attacker-specified backdoor task, while SafeStart finds that reducing active experts raises harmful compliance on some tested models and that running all experts at the response start largely reverses the increase. These are compatible but distinct results: BadMoE assumes white-box, task-specific poisoning, whereas SafeStart studies inference-time serving changes under tested jailbreaks; neither directly validates the other’s method.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2504.18598v3 — Original paper
Excerpt reference:
static/papers/2504.18598v3.md:16-59
Basis: Paper text
Source SHA-256:d03084a65b35788c54edbf2fdf4d5fe607528e31285786af96294d7aaa7abb0b2611.06147v1 — Original paper
Excerpt reference:
static/papers/2611.06147v1.md:529-596
Basis: Paper text
Source SHA-256:1d552ad92de3f34c934babf333f0d277211490666eb6387ccdb04647a39b447a2611.06147v1 — Original paper
Excerpt reference:
static/papers/2611.06147v1.md:676-747
Basis: Paper text
Source SHA-256:1d552ad92de3f34c934babf333f0d277211490666eb6387ccdb04647a39b447a
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Small language models can learn backdoors without simply copying their teachers
Source published
Shared keywords: ai security, language models
Poisoned reference answers can plant persistent rules in AI agent skills
Source published
Shared keywords: ai security
When AI security guards mistake contracts for attacks
Source published
Shared keywords: ai security, language models
AI debate partners can craft evidence that misleads automated fact-checkers
Source published
Shared keywords: ai security
The Office document you see may not be the one an AI reads
Source published
Shared keywords: ai security, language models