TRANSMISSION // 2403.01361v3
Learning one price and different advertising budgets across markets
Source published
A theoretical preprint studies how a seller can learn a shared price and market-specific advertising budgets from sales feedback. Its algorithms exploit the separation between local spending decisions, with stronger guarantees when advertising has diminishing returns.
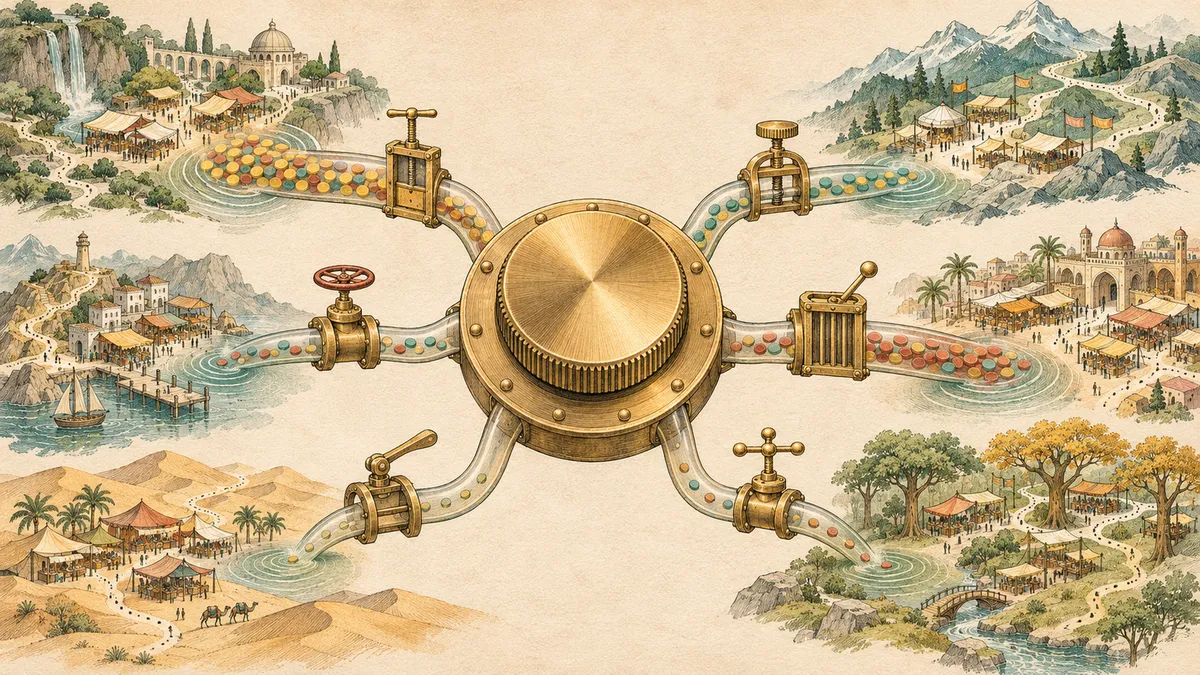
Choosing a price becomes harder when advertising changes how much people buy. A seller serving several markets must learn not only what customers will pay, but also where additional marketing expenditure is worthwhile. In the preprint “Bandit Profit-Maximization for Targeted Marketing,” Joon Suk Huh, Ellen Vitercik and Kirthevasan Kandasamy investigate this problem under a constraint: every market receives the same price.
Learning while selling
The paper considers a seller making repeated decisions over T rounds in n markets. Each round, the seller selects one common price and a separate marketing expenditure for each market. It then observes sales in every market—but only for the choices it actually made. It cannot directly see what another price or budget would have achieved.
This is a bandit-learning problem: the seller must balance exploiting choices that seem profitable against exploring alternatives. Profit is defined as sales revenue minus marketing expenditure. Prices, expenditures and demand are normalized to lie between zero and one; the stated objective does not include a separate production-cost term.
Demand can differ across markets and change over time without following a fixed statistical model. However, those changes must be non-adaptive: the sequence of demand-generating rules is selected independently of the seller’s unfolding actions. This is a demanding theoretical environment, but not one in which competitors continually react to the algorithm’s decisions.
One shared decision, many local ones
The common price ties the markets together. A price that works well in one market might perform poorly elsewhere. If each market had its own price, the seller could solve separate local problems instead.
The authors exploit a useful separation that remains despite this constraint. For any particular shared price, each market’s marketing expenditure can be optimized separately. The price can then be evaluated using the combined results of those local decisions.
Their first algorithm places prices and expenditures on grids. It maintains probabilities for choosing each price, plus separate spending probabilities for every market at each candidate price. This avoids tracking every possible combination of all budgets and the price—a collection that grows exponentially with the number of markets.
After observing sales, the algorithm updates these probabilities using a method based on exponential weighting. An important complication is that disappointing sales at one price might reflect poor advertising choices rather than a bad price. The authors therefore modify the estimated losses to control their variability and encourage further exploration, rather than discarding prices too aggressively.
What the guarantees mean
Performance is measured using expected regret: the difference between the algorithm’s cumulative profit and the expected profit of the best fixed common price and fixed collection of market-specific budgets, chosen with hindsight. The benchmark does not change its decisions every round, even though demand can change.
Under the first set of assumptions, expected demand never decreases when marketing expenditure increases and never increases when price rises. The authors prove an upper regret bound of order n times T to the three-quarter power, with an additional logarithmic factor.
Because this grows more slowly than T for a fixed number of markets, the average profit gap per round tends to zero. That is an asymptotic learning guarantee, not a promise of immediate profitability or a particular monetary return.
The authors also construct difficult demand environments to show that every algorithm must sometimes incur regret of at least order (nT) to the three-quarter power. The upper and lower results match in their power of T, but leave a factor of n to the one-quarter power unresolved, apart from logarithmic factors.
A second algorithm exploits concavity in marketing expenditure: the demand response has diminishing marginal returns. Demand must still be non-increasing in price, but need not be non-decreasing in expenditure. The method smooths probability distributions over spending choices using techniques from bandit convex optimization.
Here, the upper regret bound improves to order n times T to the two-thirds power, again with a logarithmic factor. A matching lower bound without that factor establishes that this rate is optimal up to logarithmic terms within the model.
Where the model stops
These are mathematical guarantees, not results from advertising campaigns or business trials. A key assumption is that a market’s expected demand depends only on its own marketing expenditure and the common price. Spending spillovers between markets are excluded, although random sales fluctuations across markets may be correlated.
The paper also gives adaptations for promotional credits, discrete marketing alternatives such as webpage variants, and subscription services with a specified customer-retention model. These extend the framework under explicit assumptions; they do not establish performance for arbitrary customer behavior.
The preprint’s central contribution is a way to organize learning around a shared price without treating every combination of local budgets as a separate experiment. Whether its assumptions and finite-time performance suit an actual business remains a separate empirical question.
- bandit learning
- targeted marketing
- dynamic pricing
- advertising expenditure
- regret bounds
- online optimization
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.